kubernetes overview
Architecture#
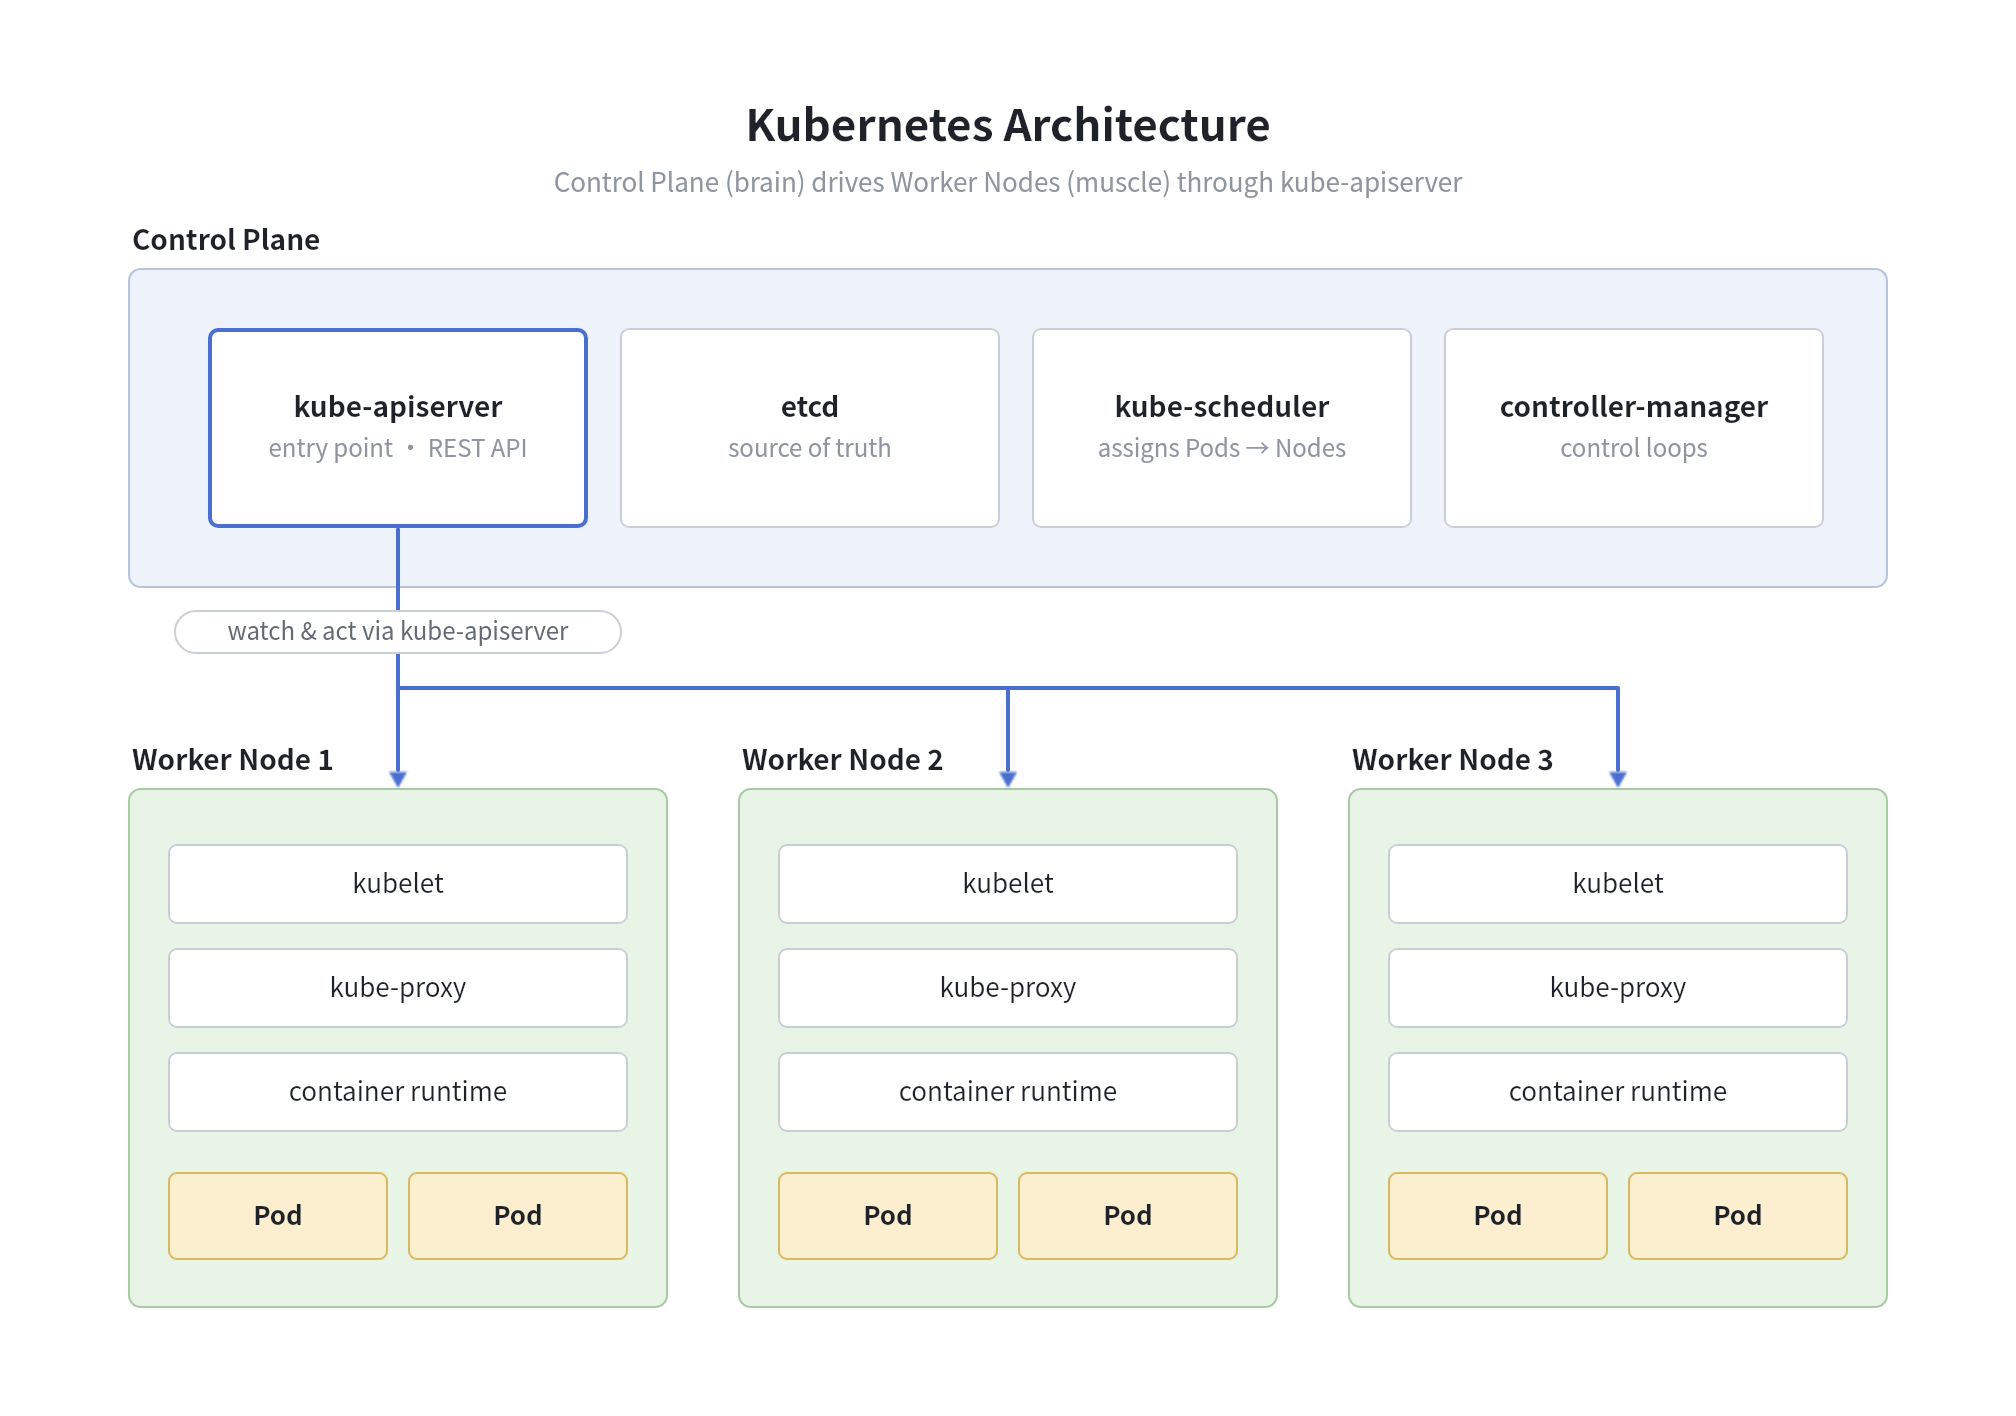
Kubernetes has two main parts: the Control Plane (brain) and Worker Nodes (muscle).
Control Plane Components#
| Component | Role |
|---|---|
| kube-apiserver | Single entry point for all operations. Validates requests, persists to etcd, serves the REST API |
| etcd | Distributed key-value store. The source of truth — all cluster state lives here |
| kube-scheduler | Watches for unscheduled Pods, assigns them to a Node based on resources and constraints |
| kube-controller-manager | Runs control loops: Node controller, ReplicaSet controller, Endpoint controller, etc. |
| cloud-controller-manager | Cloud-specific logic (load balancers, storage, node lifecycle) — only in cloud deployments |
Worker Node Components#
| Component | Role |
|---|---|
| kubelet | Agent on every node. Ensures containers described in PodSpecs are running and healthy |
| kube-proxy | Maintains network rules (iptables/ipvs) to implement Service abstraction |
| container runtime | Actually runs containers. k8s talks to it via CRI (e.g. containerd, CRI-O) |
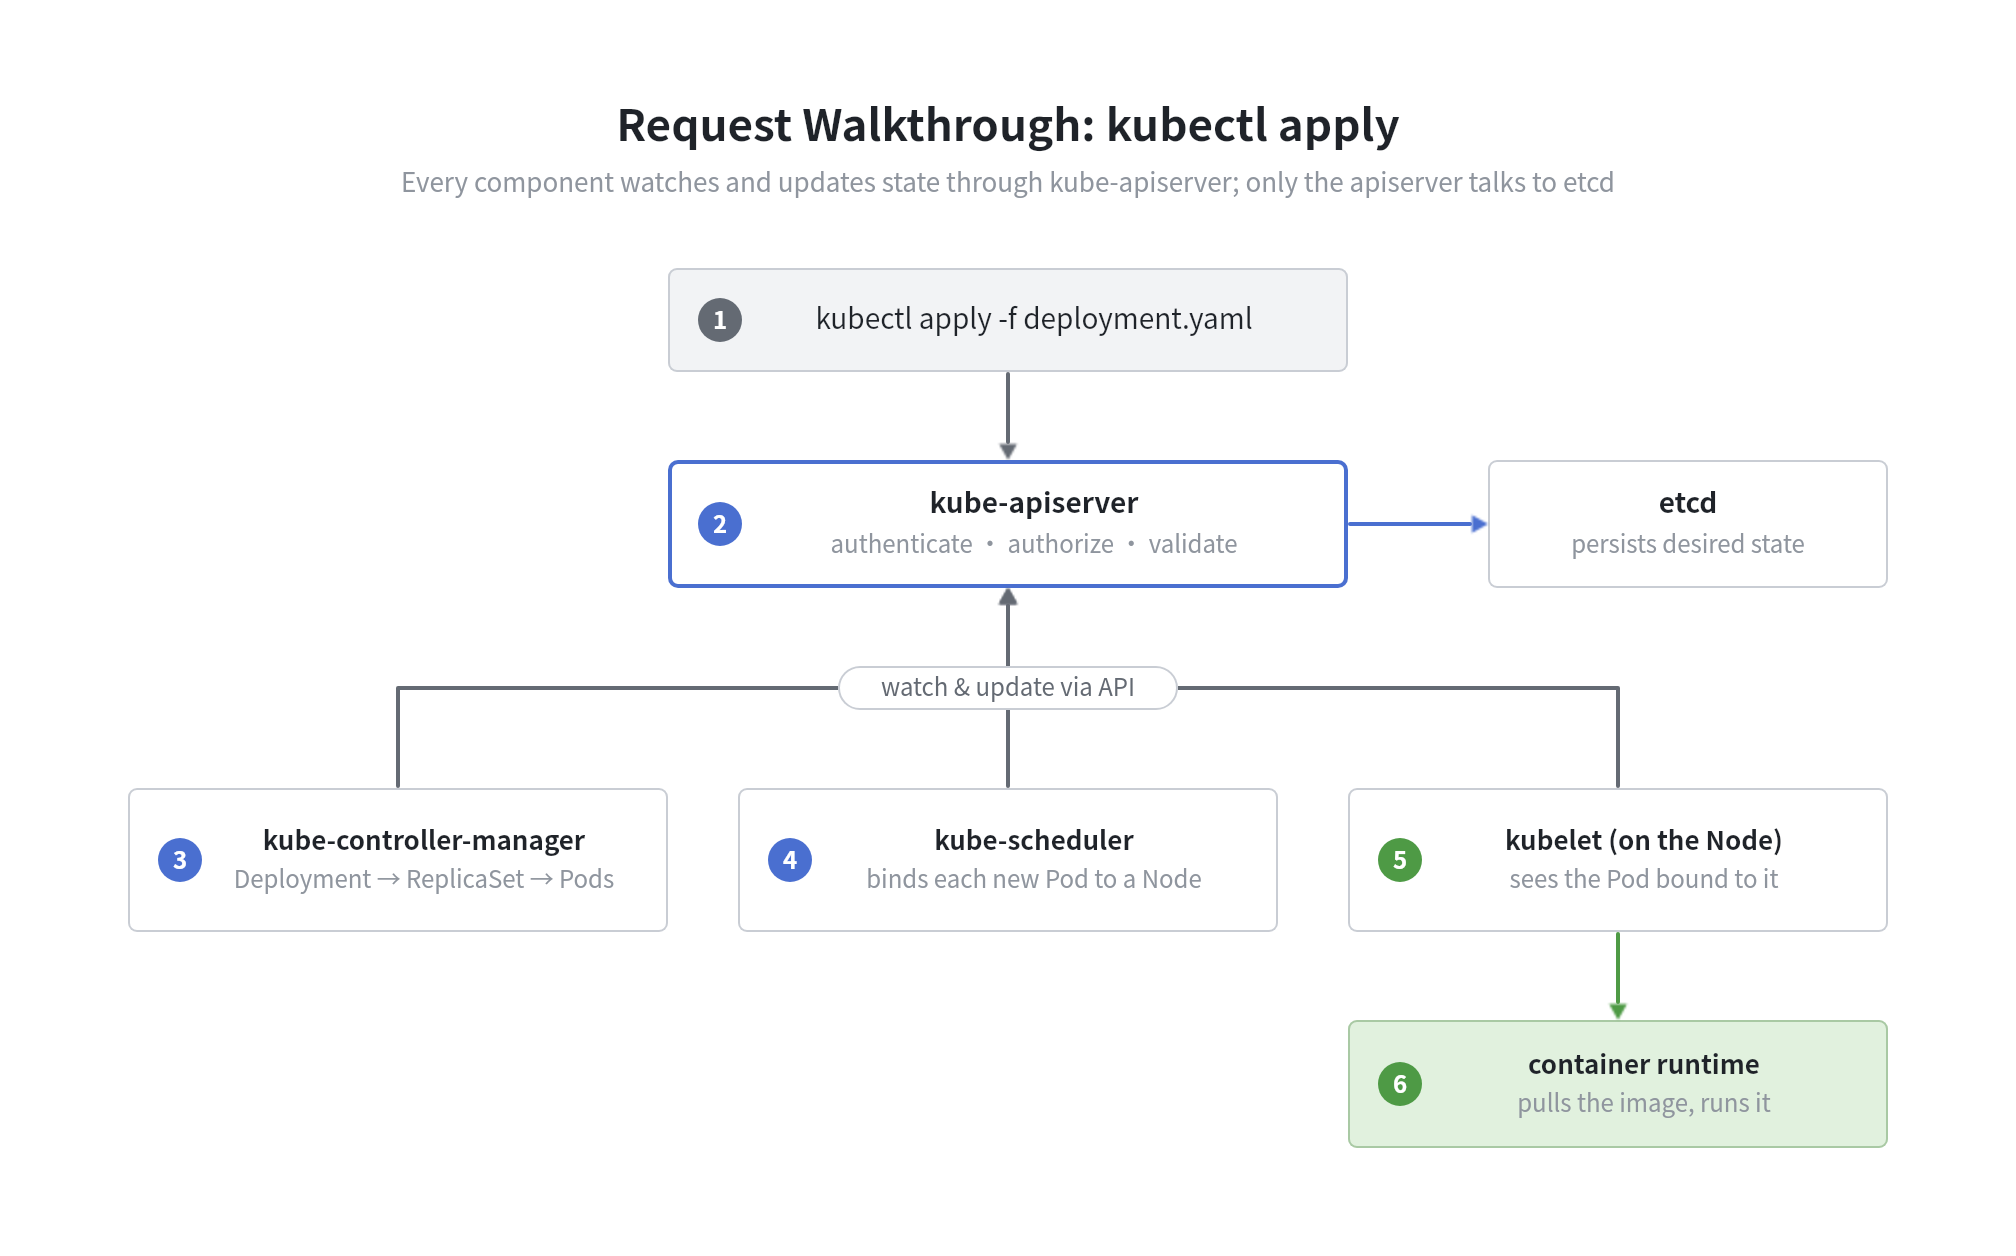
How They Interact (a request walkthrough)#
Key Concepts#
Workload Resources#
| Resource | Use Case |
|---|---|
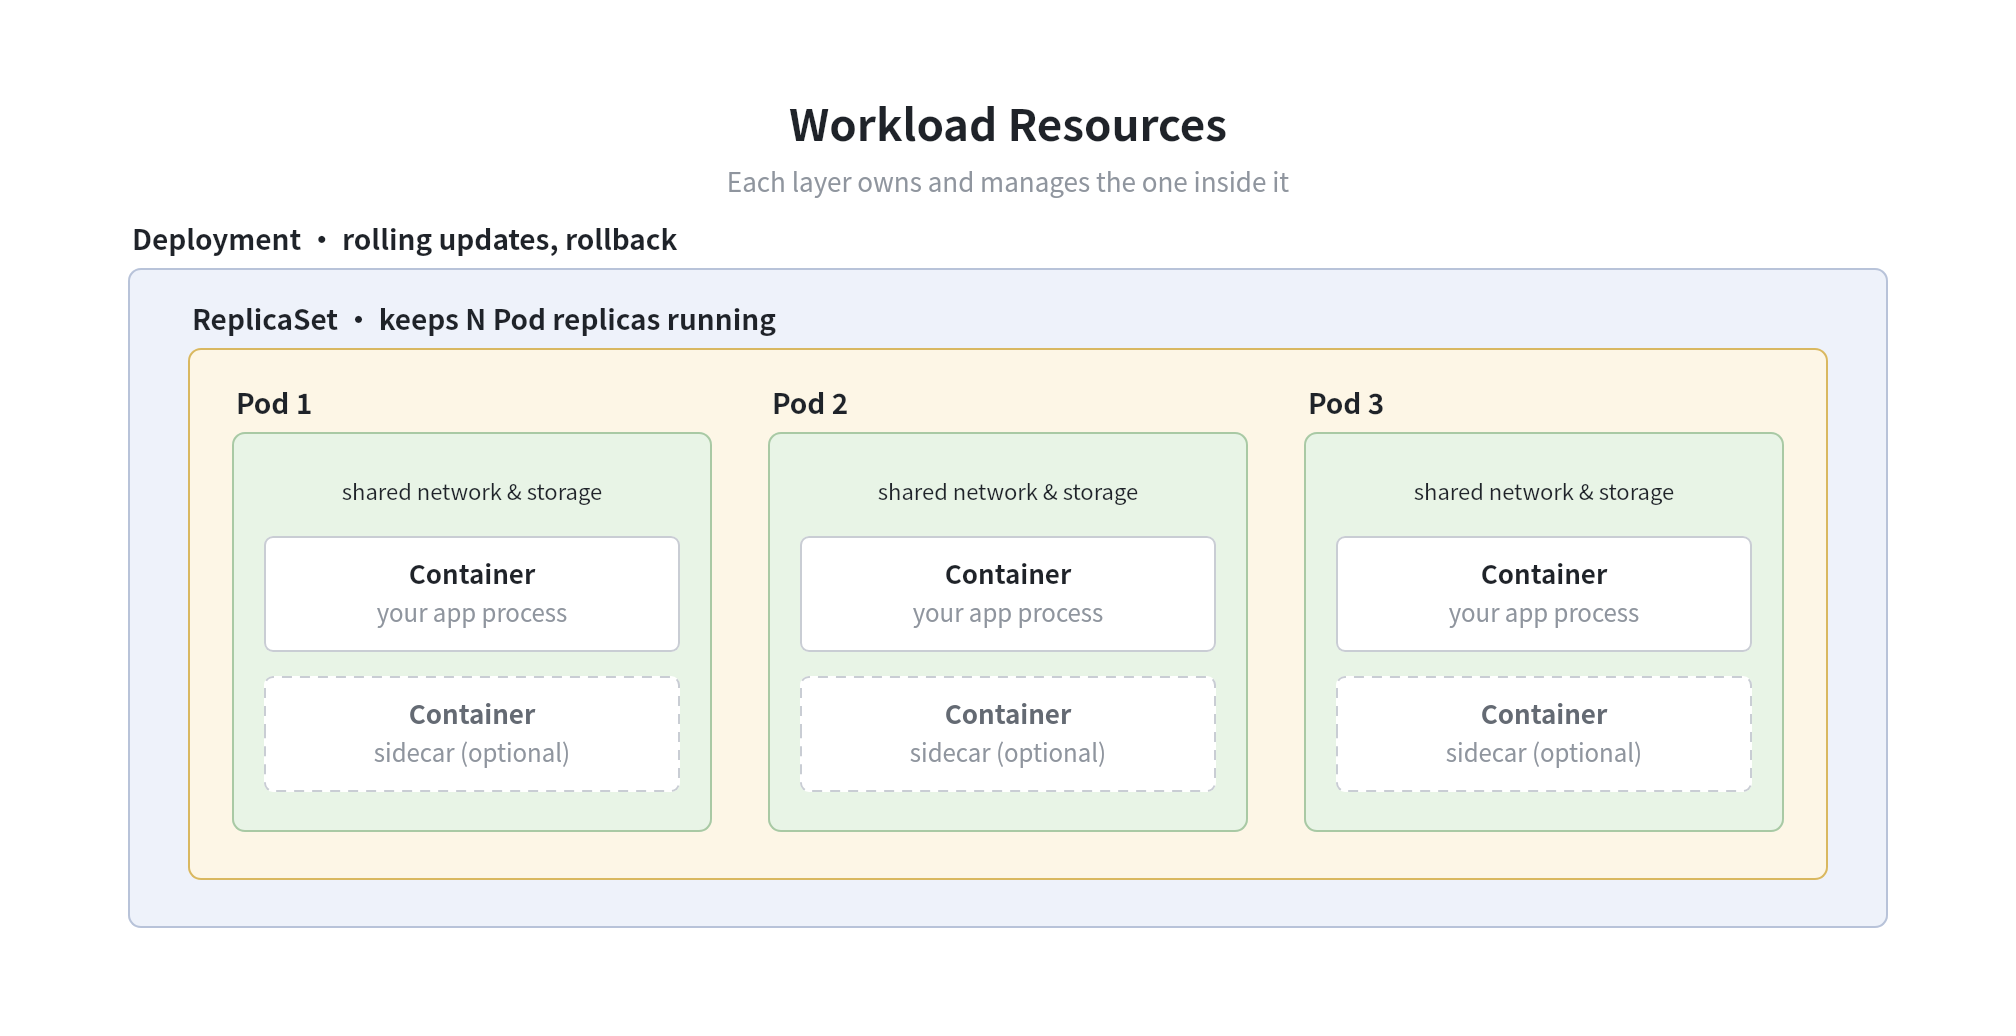
| Pod | Runs one or more tightly-coupled containers |
| ReplicaSet | Keeps N replicas of a Pod running (usually managed by Deployment) |
| Deployment | Stateless apps — rolling updates, rollback, scaling |
| StatefulSet | Stateful apps (databases) — stable network identity, ordered operations |
| DaemonSet | Run one Pod per node — log collectors, monitoring agents |
| Job | Run to completion — batch tasks |
| CronJob | Scheduled Jobs |
Service & Networking#
A Service gives a stable IP/DNS to a set of Pods (selected by labels). Pods come and go; Service stays.
| Service Type | Scope | Use Case |
|---|---|---|
| ClusterIP | Internal only | Default; Pod-to-Pod communication |
| NodePort | External via NodeIP:Port |
Simple external access, dev/testing |
| LoadBalancer | External via cloud LB | Production external traffic (cloud) |
| ExternalName | DNS alias | Point to external service by DNS |
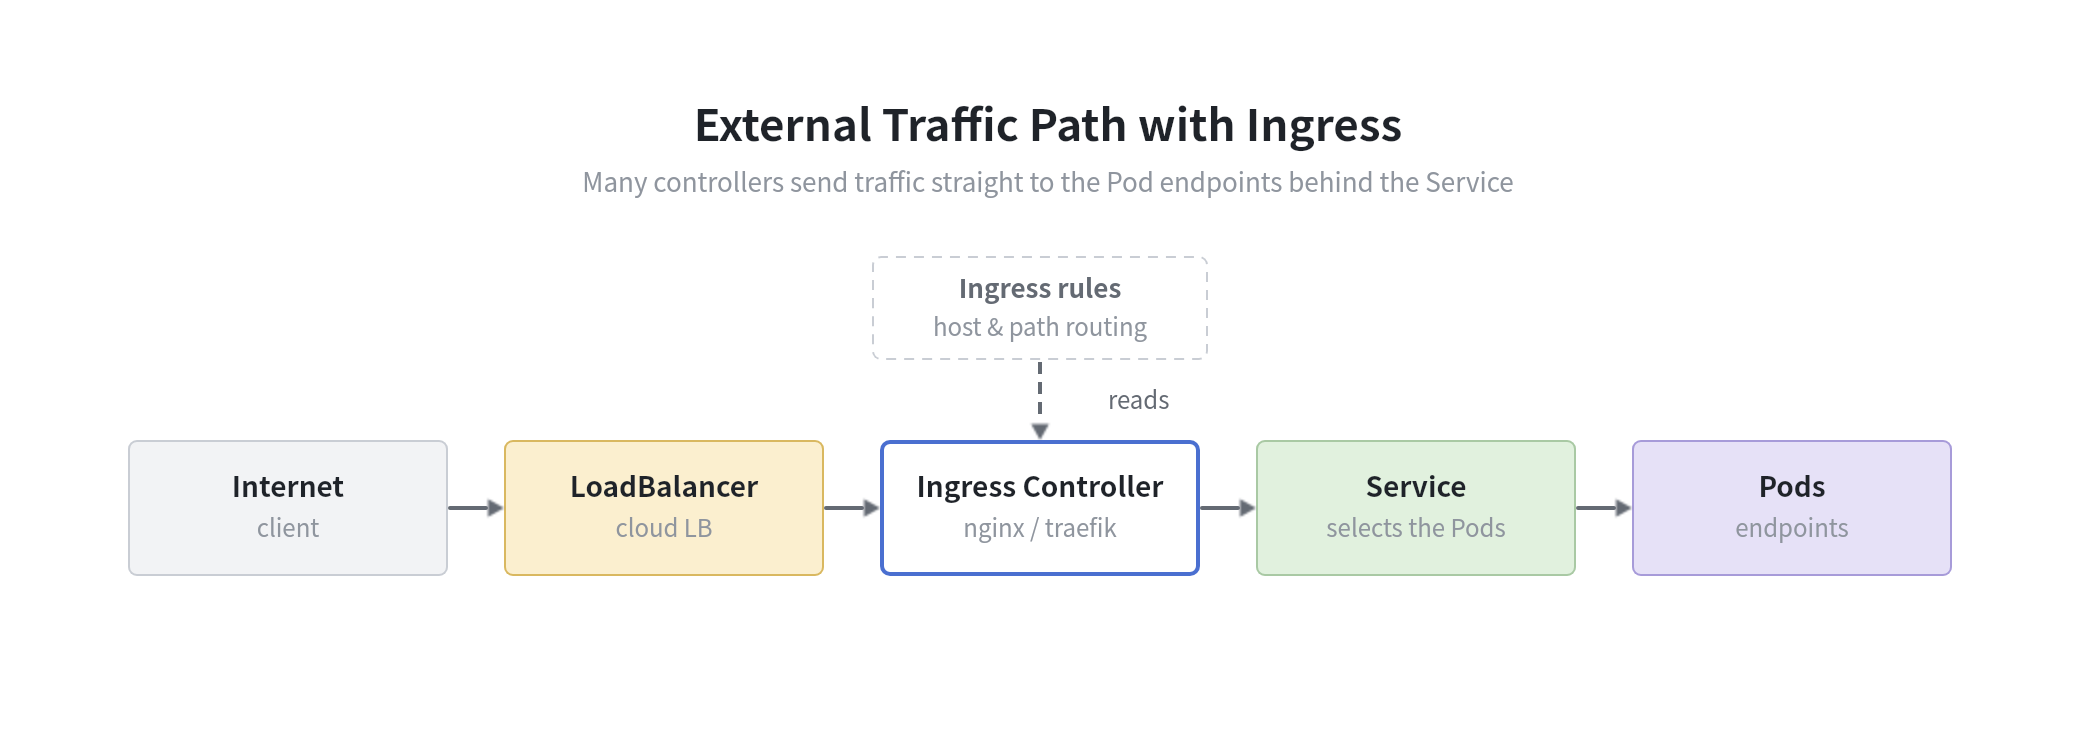
Ingress = HTTP/HTTPS routing rules (path-based, host-based) sitting in front of Services. Requires an Ingress Controller (e.g. nginx, traefik).
Gateway API (GA since k8s 1.31, gateway.networking.k8s.io/v1) is the successor to Ingress — more expressive, supports TCP/UDP/gRPC, role-based split between infra and app teams. Ingress is still supported but new deployments should prefer Gateway API.
Config & Storage#
| Resource | Purpose |
|---|---|
| ConfigMap | Non-sensitive config — env vars, config files |
| Secret | Sensitive data — passwords, tokens (base64 encoded, not encrypted by default) |
| PersistentVolume (PV) | A piece of storage provisioned in the cluster |
| PersistentVolumeClaim (PVC) | A request for storage by a Pod — binds to a matching PV |
| StorageClass | Defines how to dynamically provision PVs |
Metadata & Organization#
- Namespace — virtual cluster within a cluster, isolates resources by team/env
- Label — key-value pairs on resources (
app: nginx,env: prod) - Selector — query labels to target resources (
app: nginx) - Annotation — non-identifying metadata (deployment tools, git SHA, etc.)
Security#
| Resource | Purpose |
|---|---|
| ServiceAccount | Identity for a Pod to authenticate with the API server |
| Role / ClusterRole | Defines permissions (verbs on resources) |
| RoleBinding / ClusterRoleBinding | Grants a Role to a ServiceAccount/User |
Key Design & Philosophy#
1. Declarative, Not Imperative#
You describe what you want (desired state), not how to get there.
# declarative: "I want 3 nginx pods"
spec:
  replicas: 3

# vs imperative: "start 3 nginx pods right now"
kubectl run nginx-1 ...
kubectl run nginx-2 ...
kubectl run nginx-3 ...
k8s continuously works to make actual state = desired state.
2. Control Loop (Reconciliation)#
Every controller runs an infinite loop:
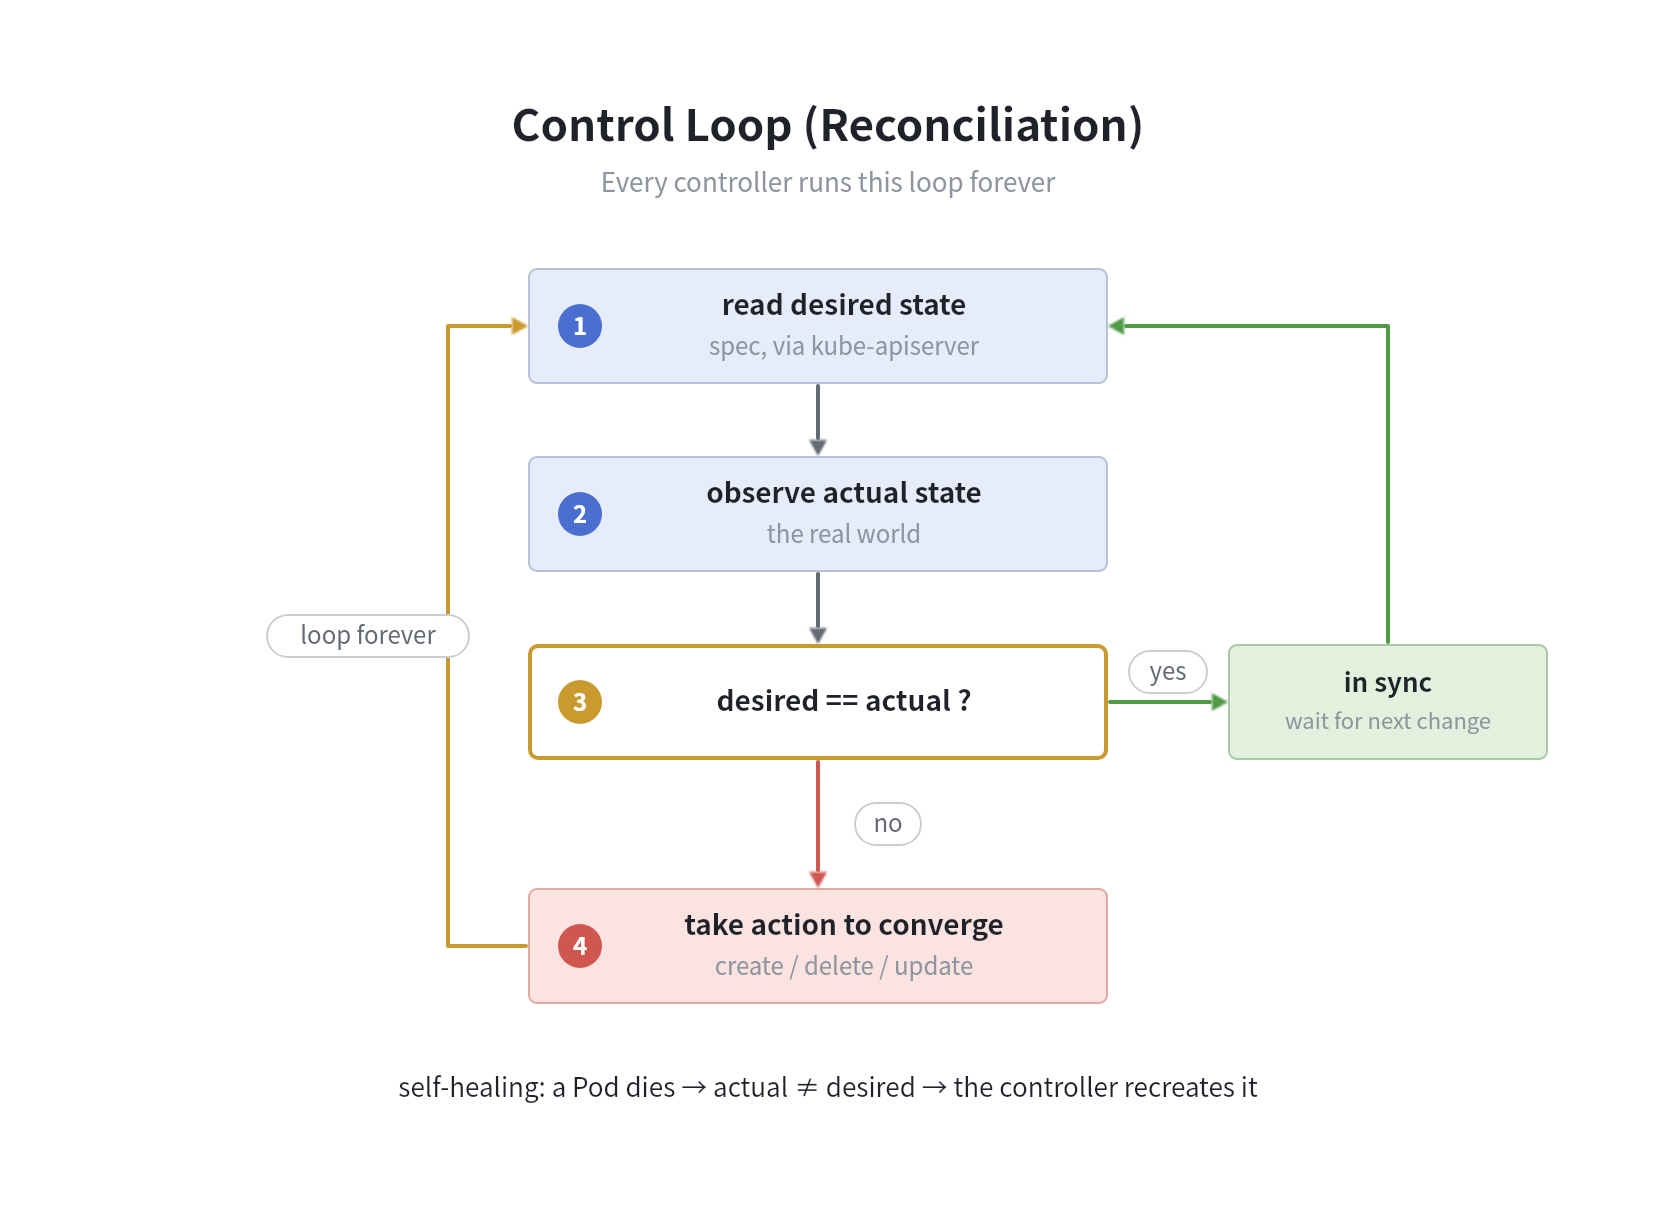
This is why k8s is self-healing — if a Pod dies, the controller notices and creates a new one.
3. Everything is an API Resource#
k8s is fundamentally an API. Every object (Pod, Service, Deployment) is a REST resource. This makes it:
- Extensible via CustomResourceDefinitions (CRD) — define your own resource types
- Automatable — everything
kubectldoes, you can do via API
4. Loose Coupling via Labels & Selectors#
Components don’t reference each other by name. A Service doesn’t know which specific Pods it routes to — it selects by labels.
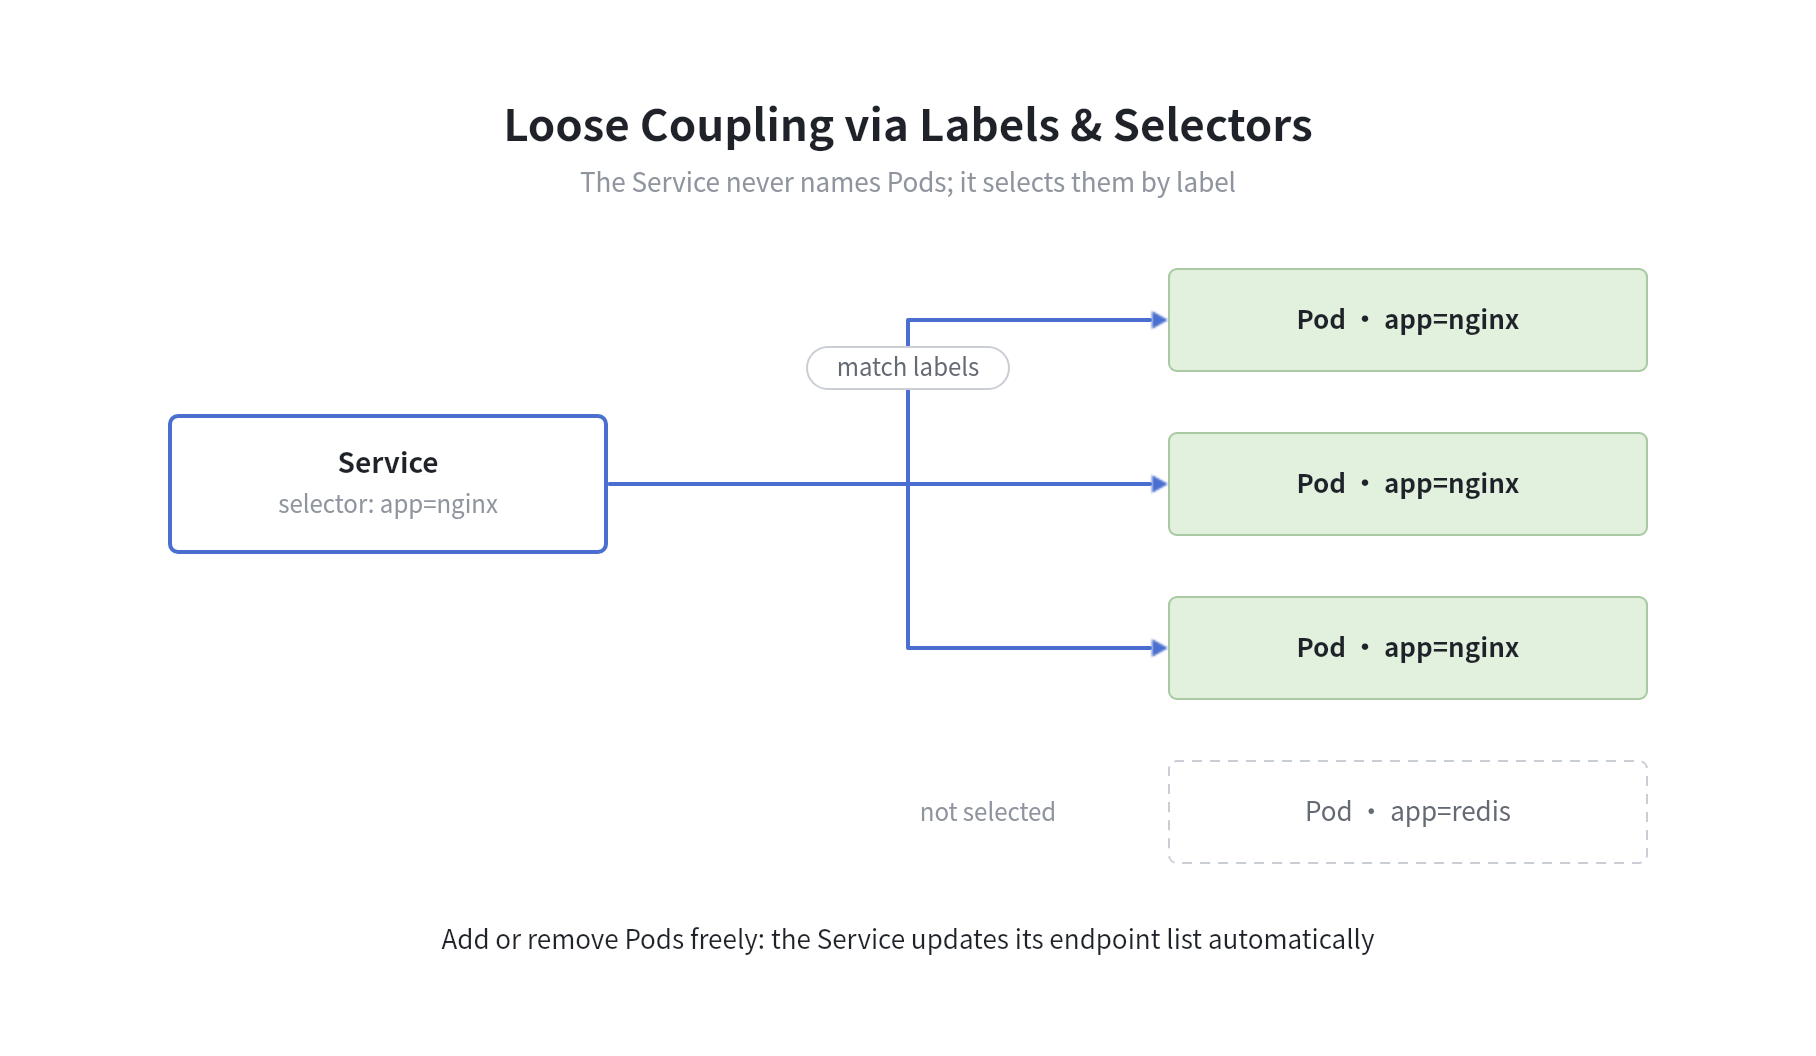
Add/remove Pods freely — the Service automatically updates its endpoint list.
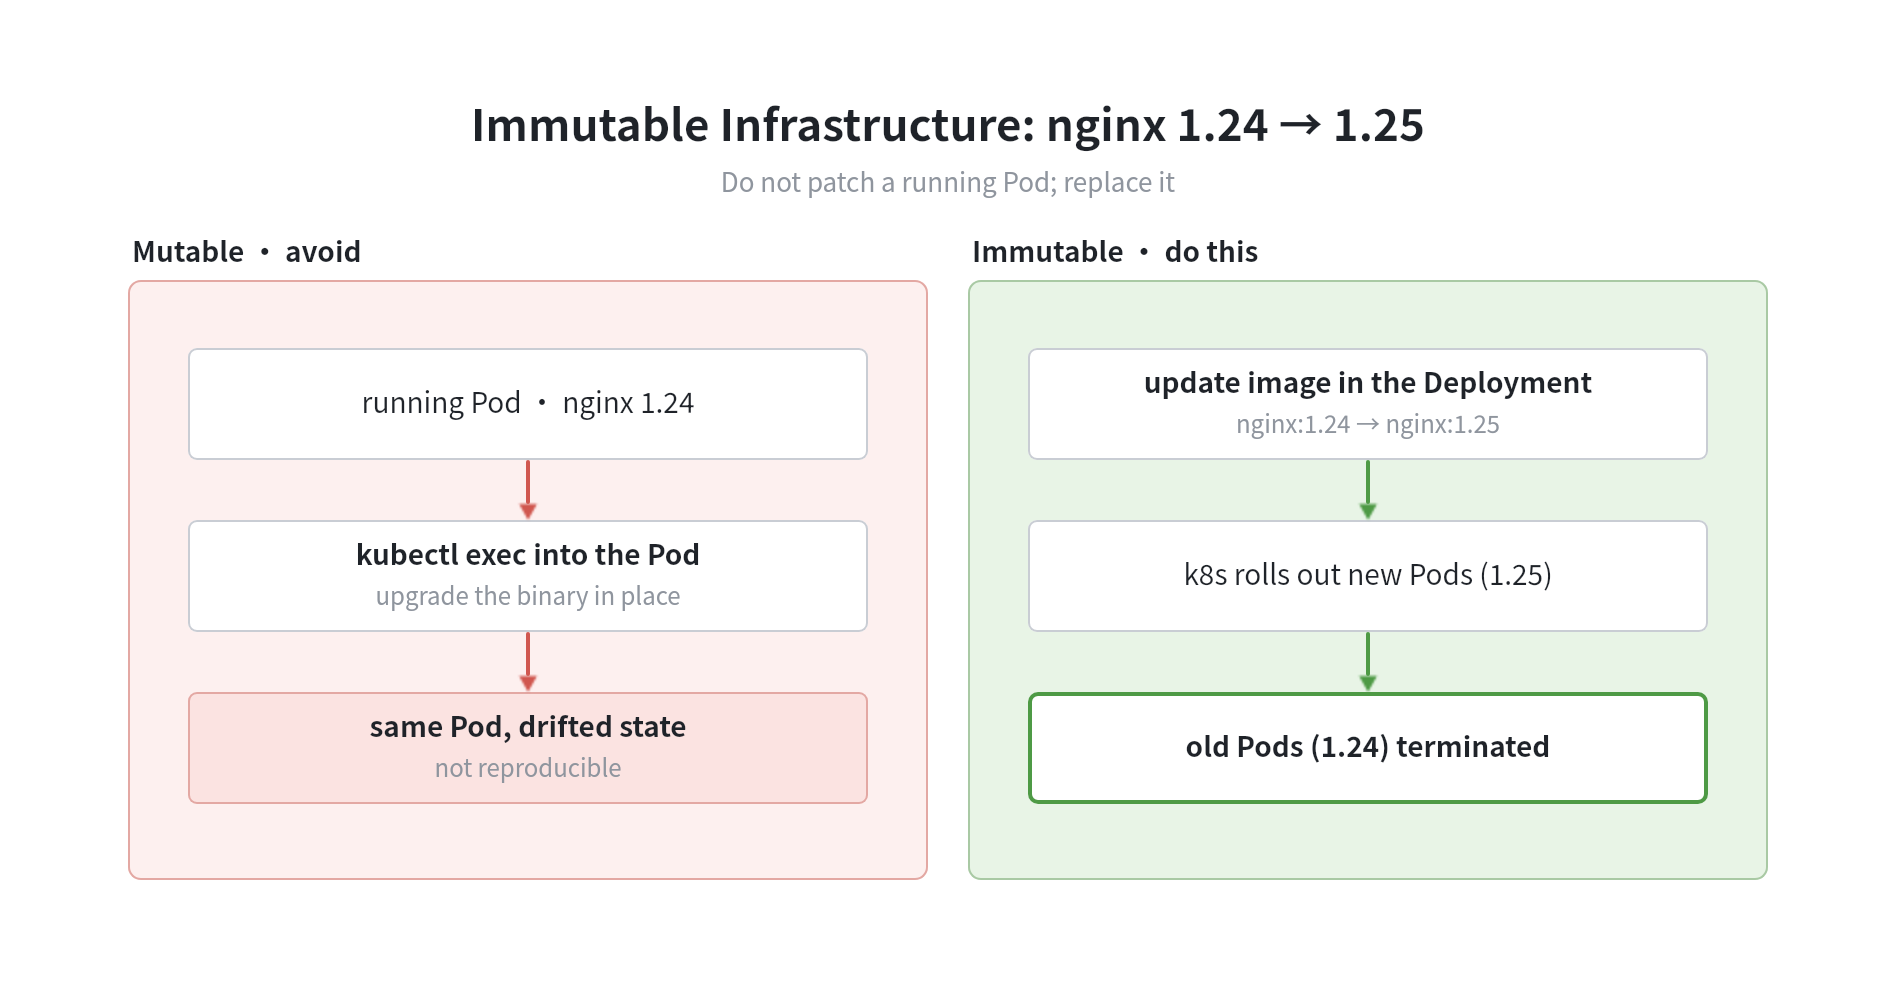
5. Immutable Infrastructure#
Don’t patch a running Pod. Replace it with a new one.
6. Single Responsibility#
Each component does one thing: scheduler only schedules, kubelet only manages local pods, etc. This composability allows swapping components (e.g. different schedulers, CNI plugins).
Fundamentals#
Linux Primitives Under the Hood#
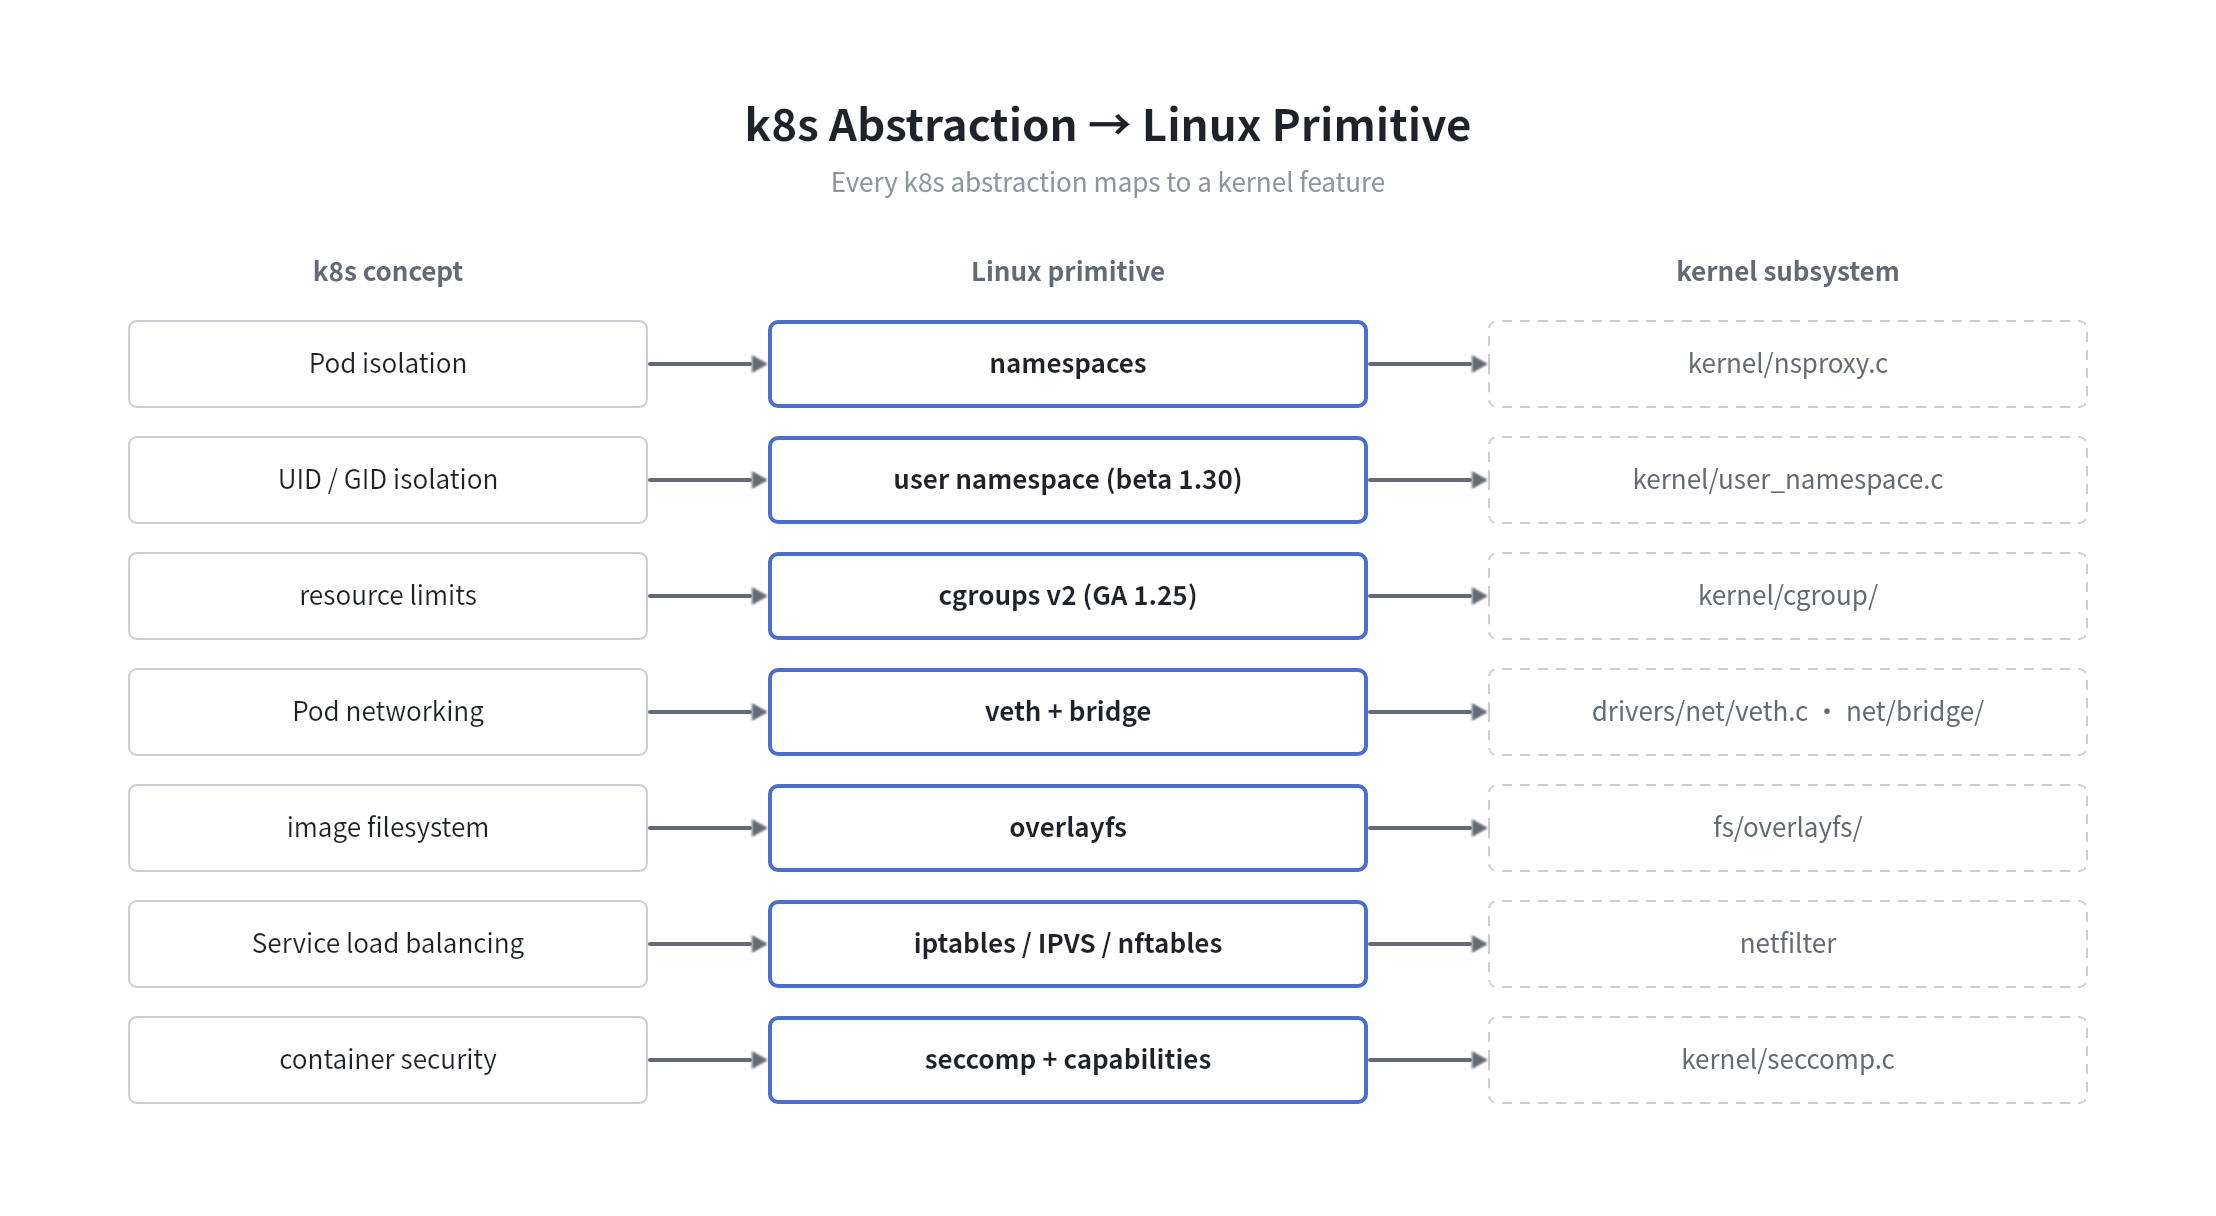
Every k8s abstraction maps to a Linux kernel feature. Understanding this makes k8s behavior much less magical.
Linux Namespaces → Pod Isolation#
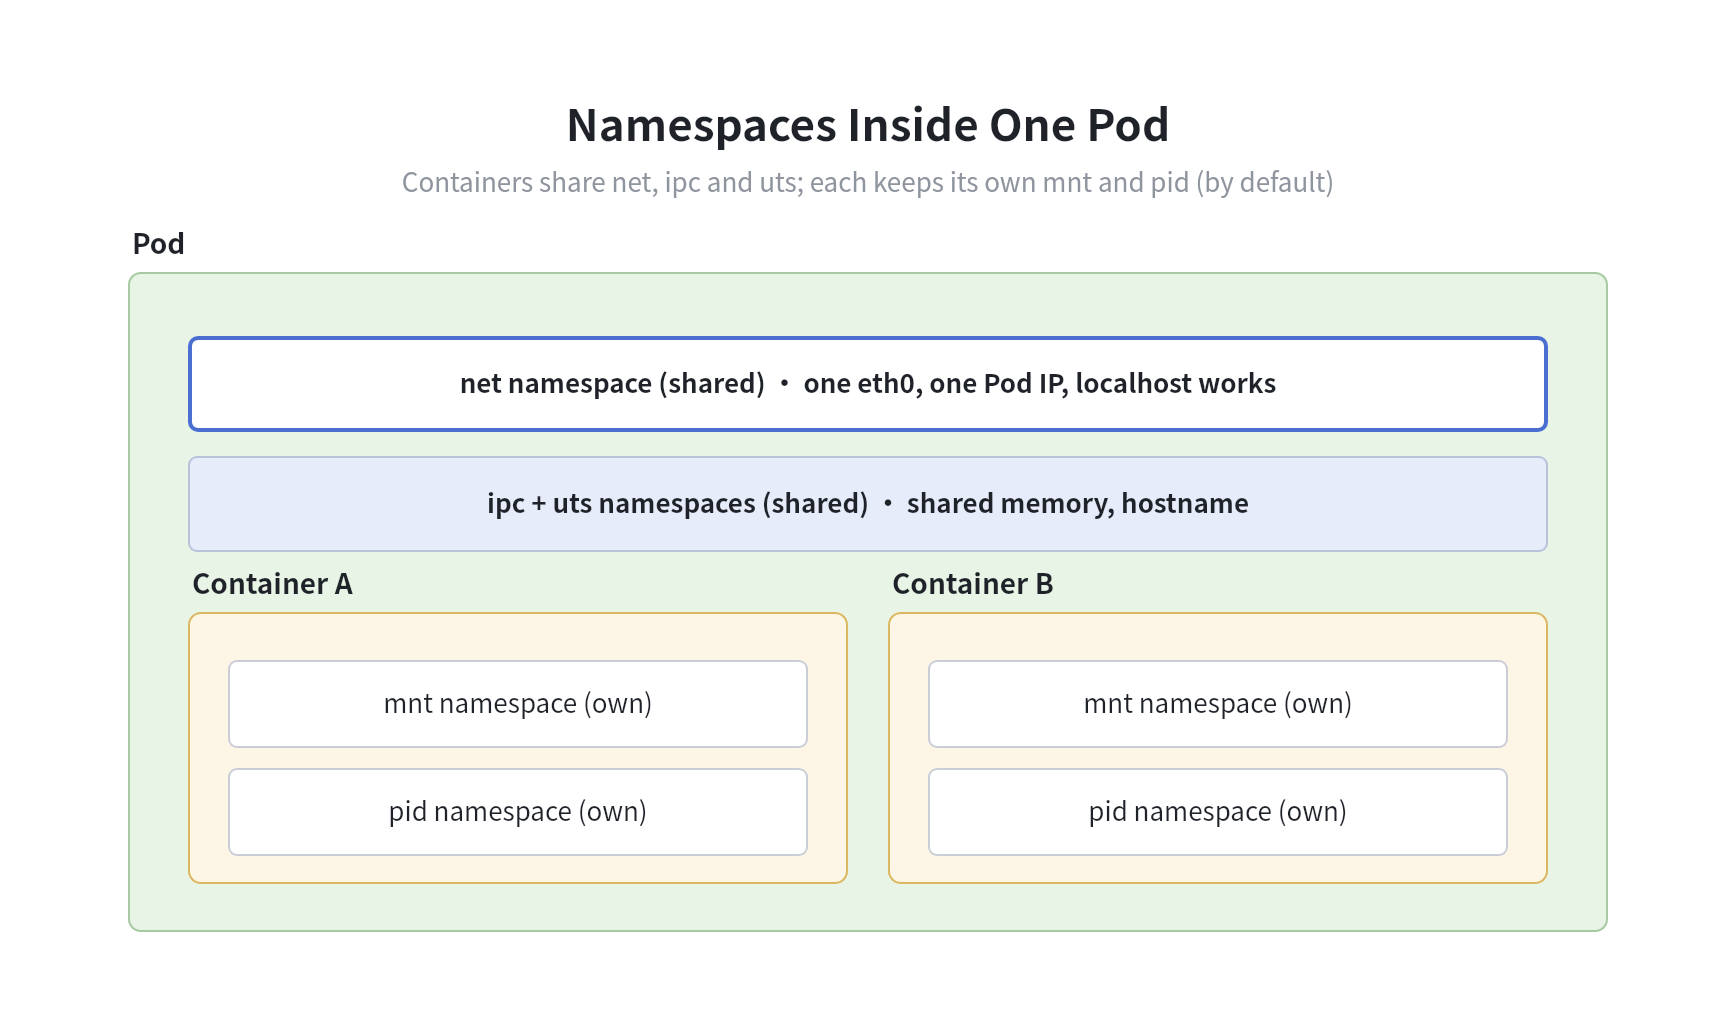
A namespace partitions a global kernel resource so each process sees its own isolated view. When k8s creates a Pod, the container runtime creates a set of namespaces for it:
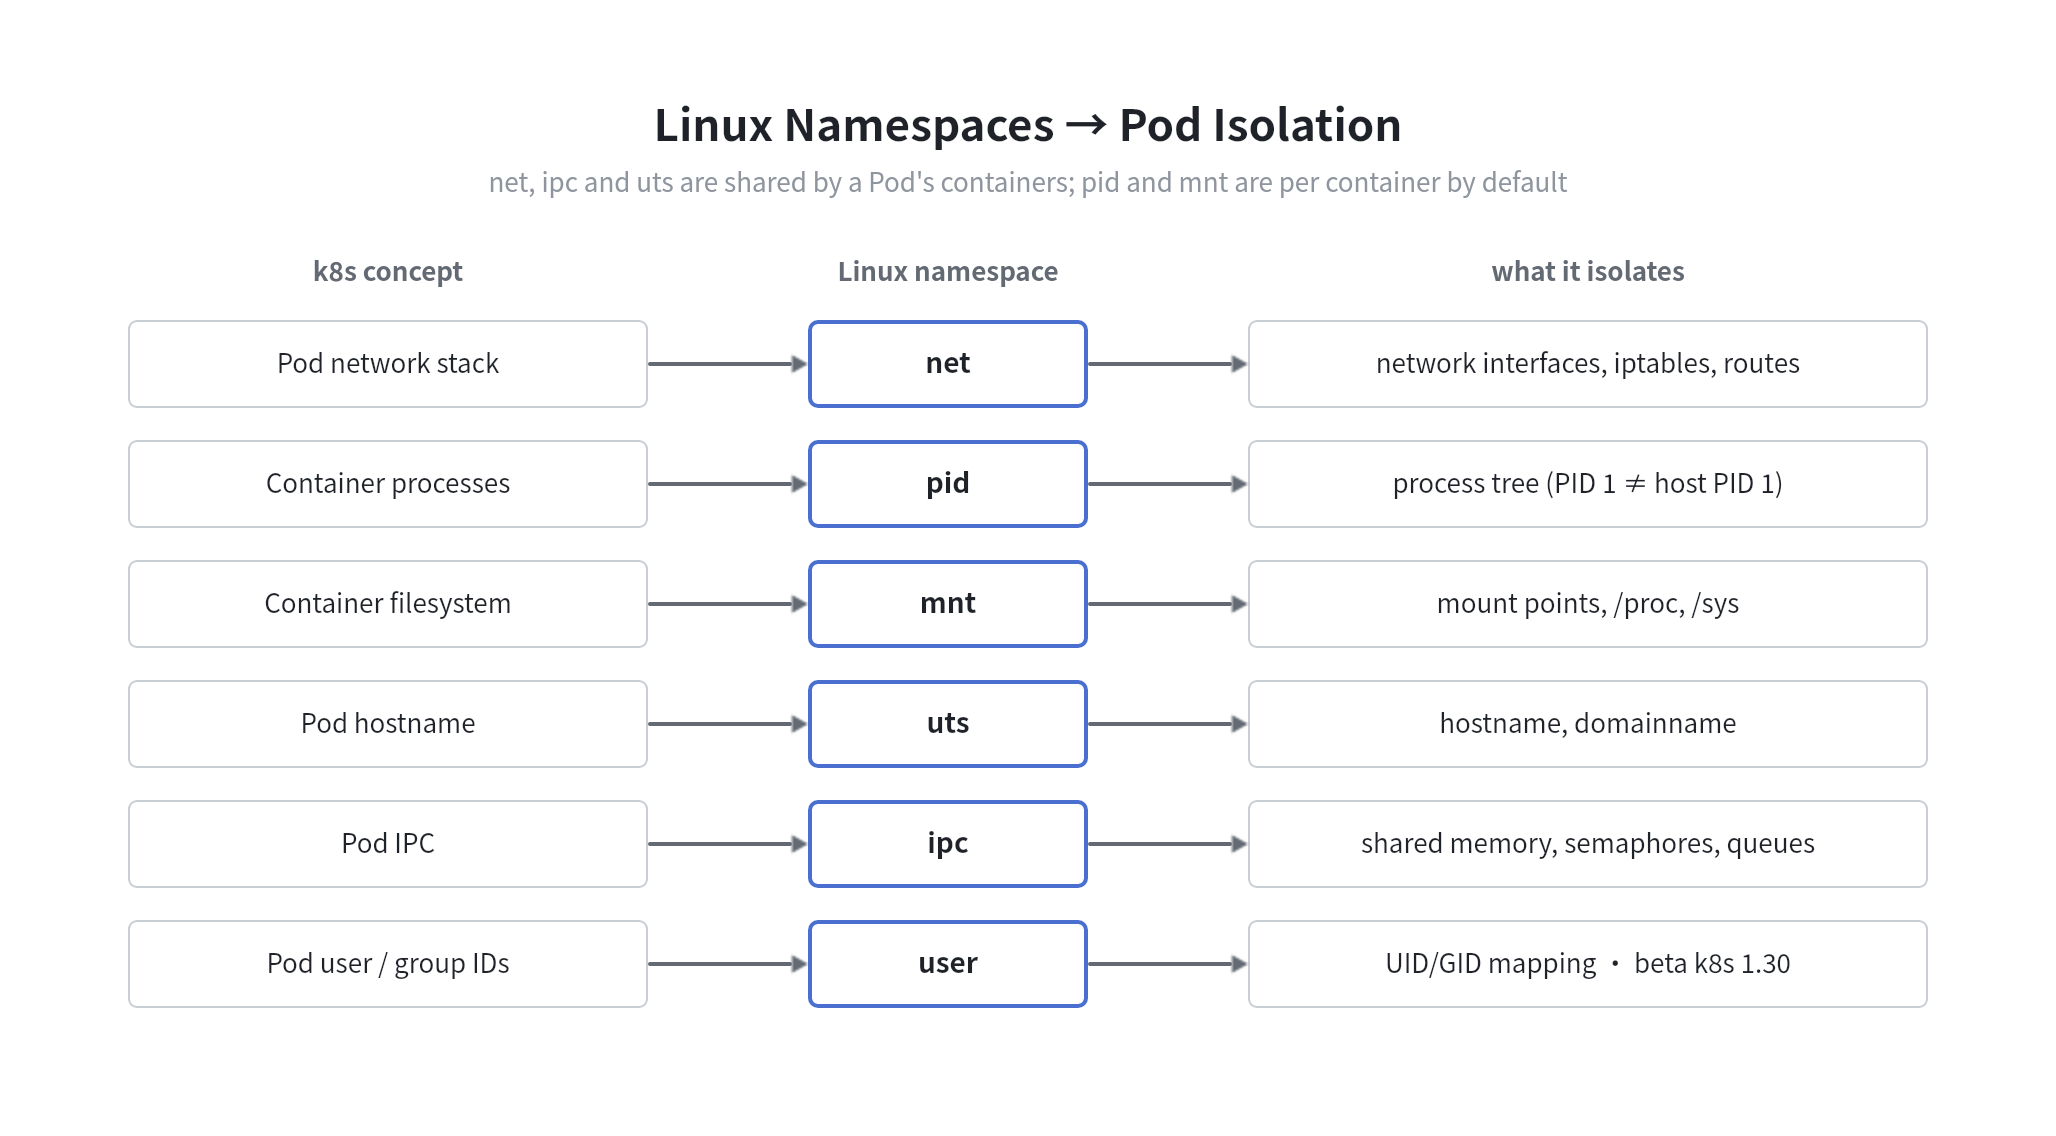
Two containers in the same Pod share the net and ipc namespaces — that’s why they can talk via localhost and share memory. Each container gets its own mnt namespace.
Verify on the host:
# find the PID of a container process on the host
crictl inspect <container-id> | grep pid

# see its namespaces
ls -la /proc/<pid>/ns/
# net -> net:[4026531992]   ← same net ns as other containers in the pod
# mnt -> mnt:[4026532xxx]   ← unique per container
cgroups → resource.requests/limits#
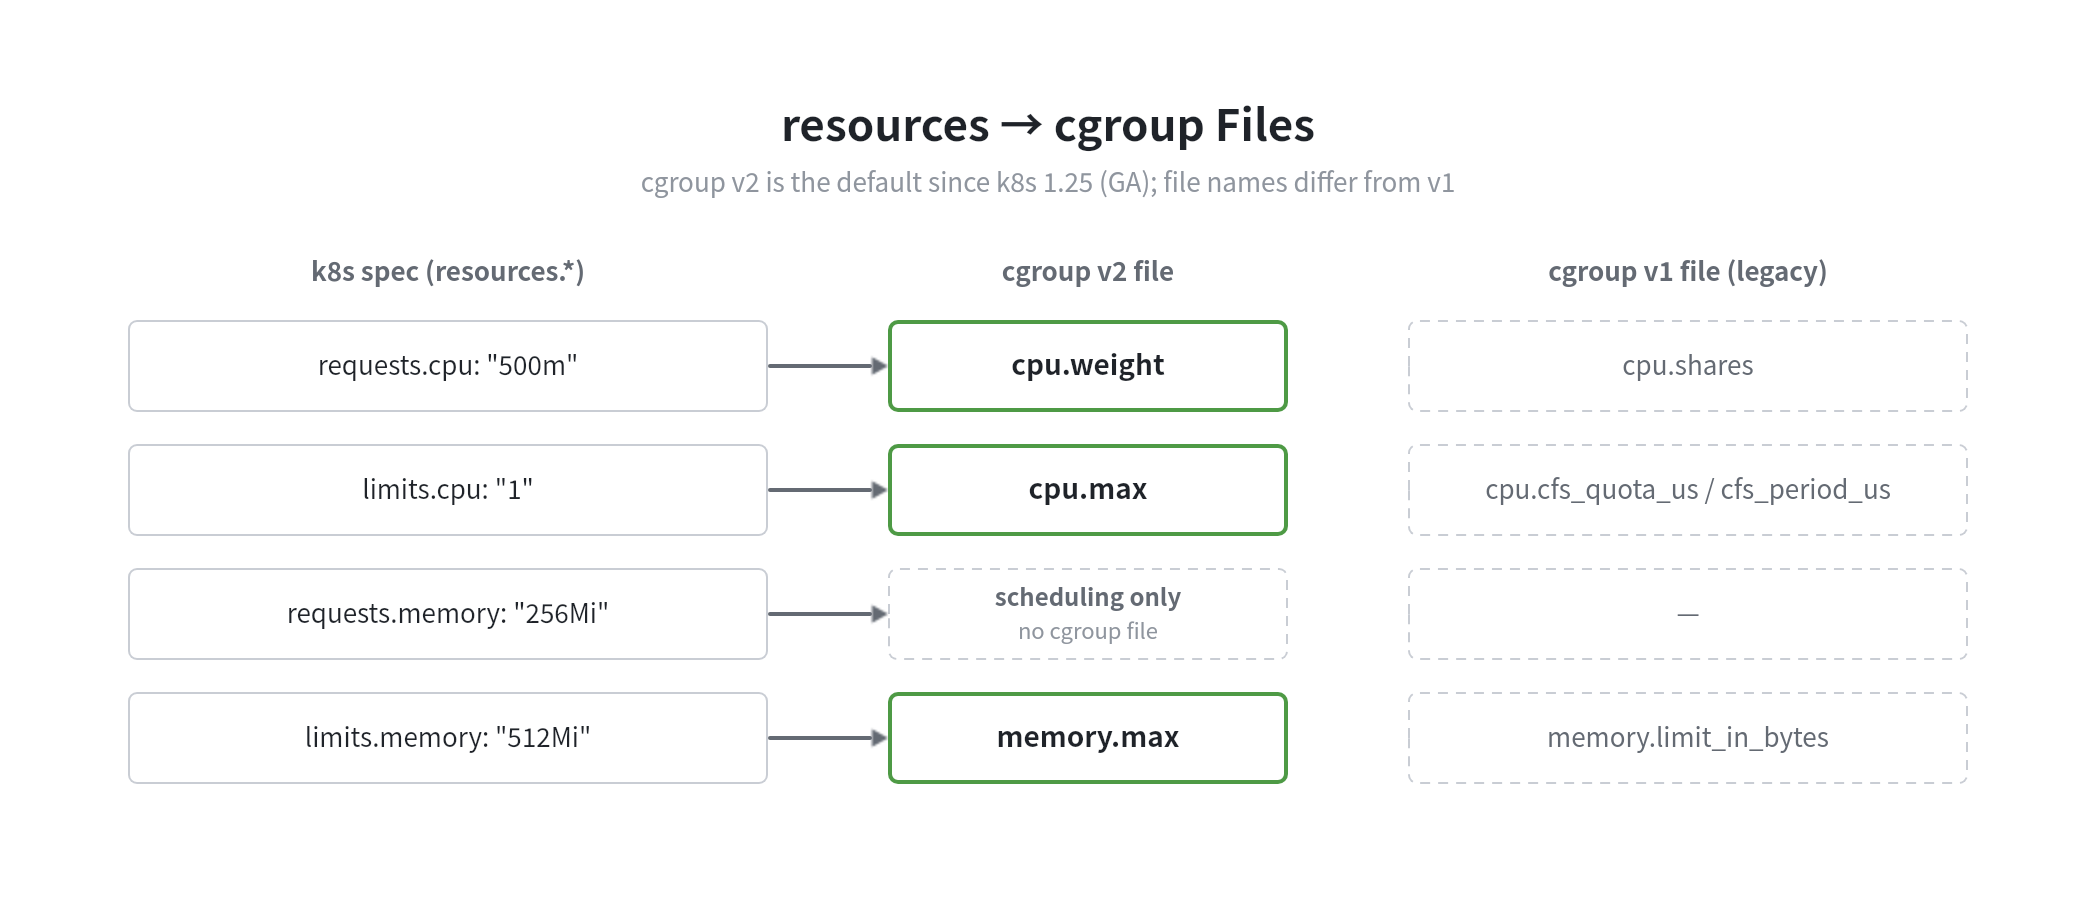
cgroups (control groups) limit and account for resource usage. When you set resources in a Pod spec, kubelet translates them to cgroup config:
cgroups v2 is the default since k8s 1.25 (GA). File names differ from v1:
cgroup hierarchy on the node (cgroupv2 + systemd):
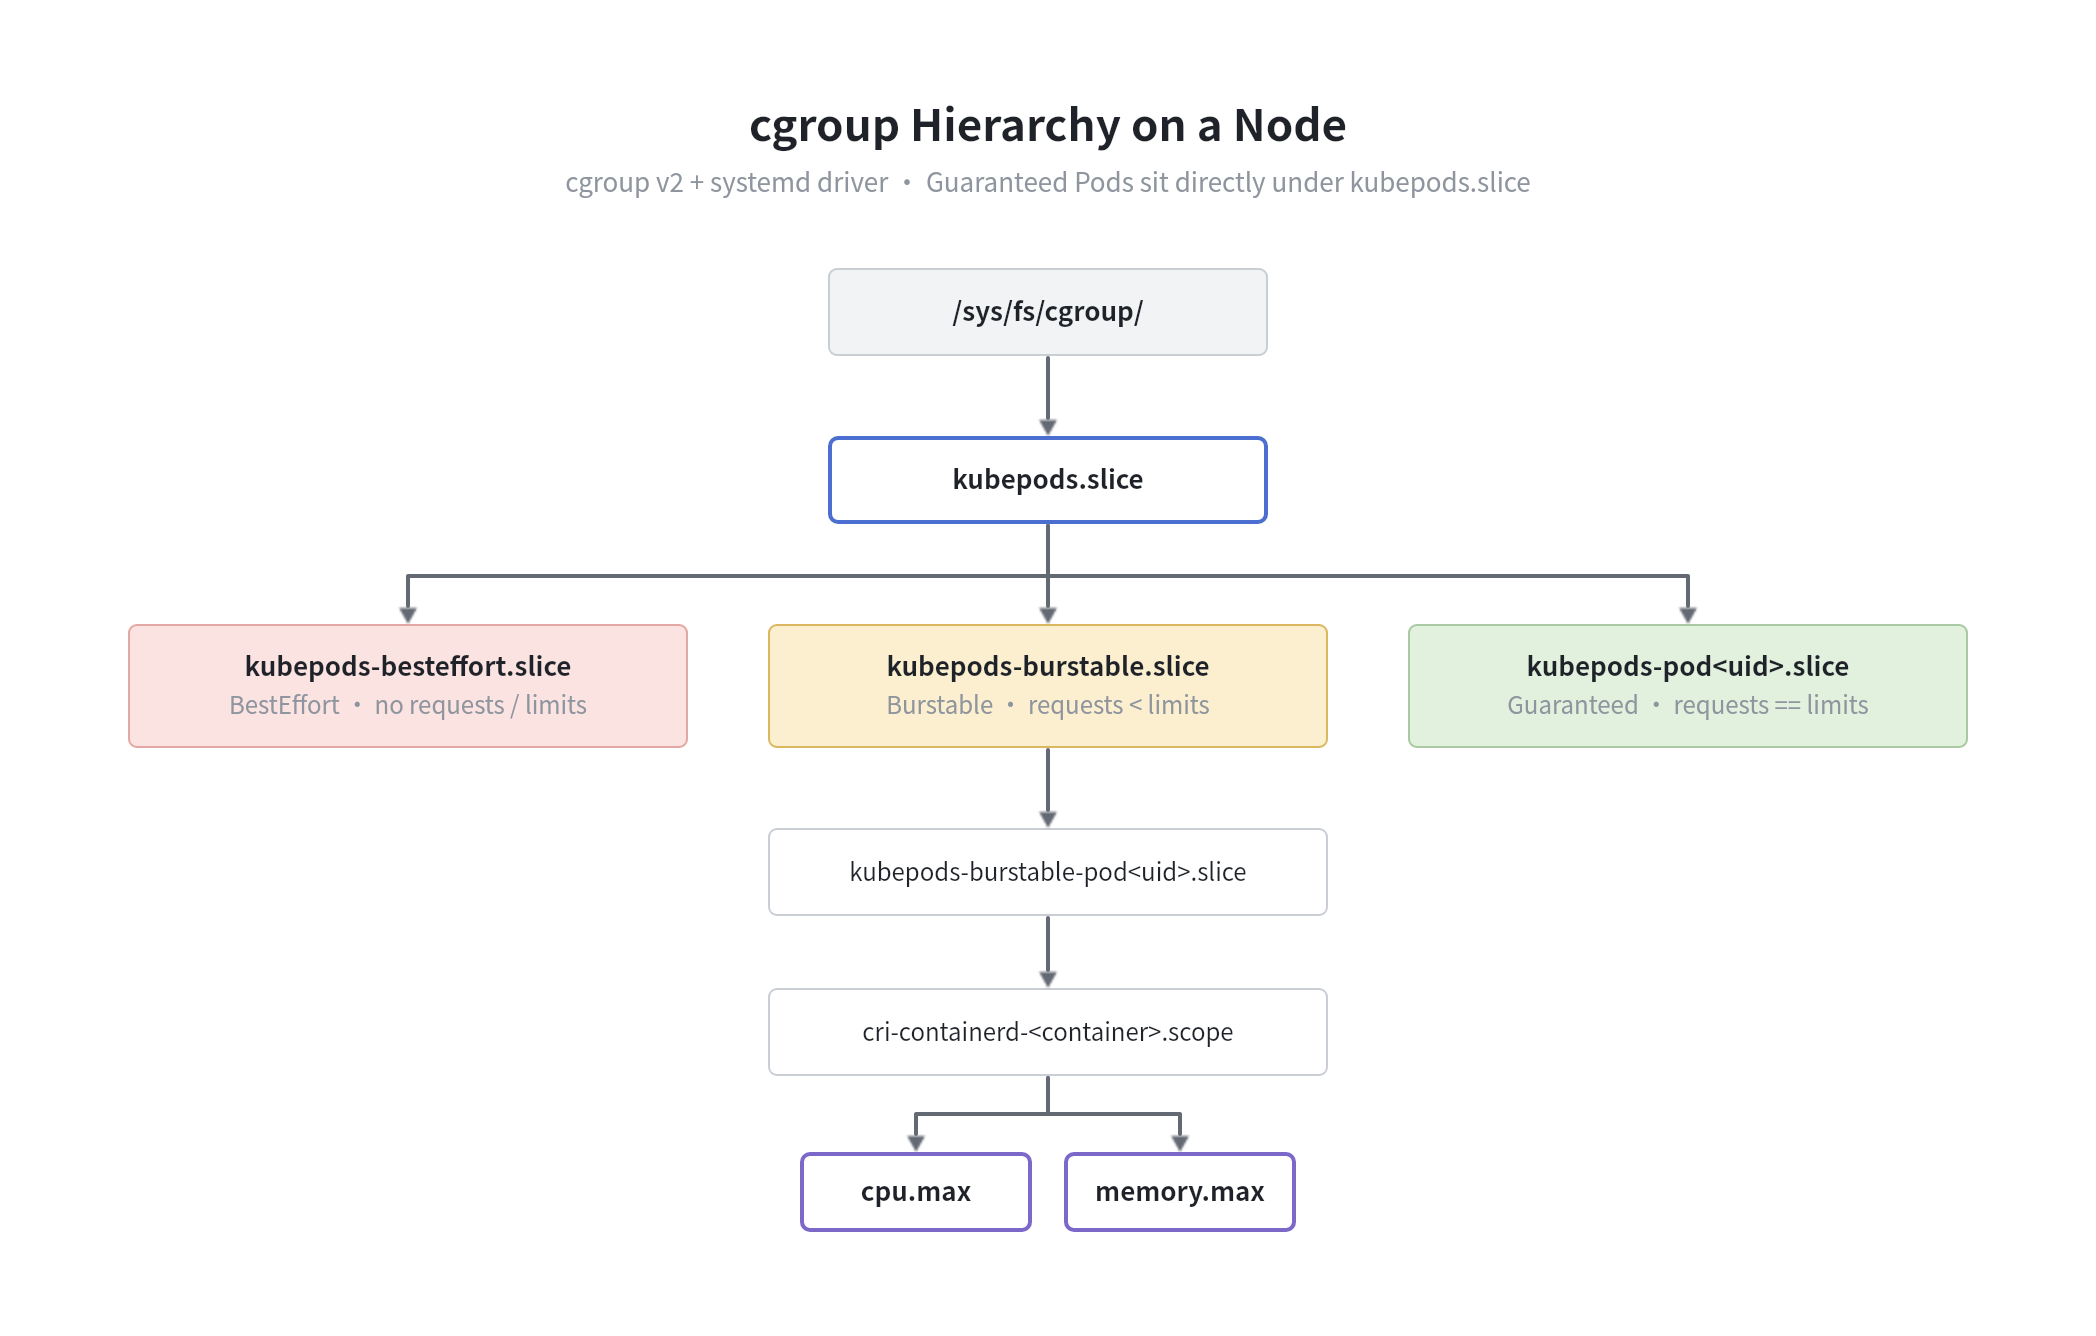
QoS class matters: when node is under memory pressure, BestEffort pods are OOM-killed first, then Burstable, never Guaranteed.
veth pairs + bridge → Pod networking#
Each Pod gets its own network namespace with a virtual ethernet interface. The CNI plugin wires it to the host:
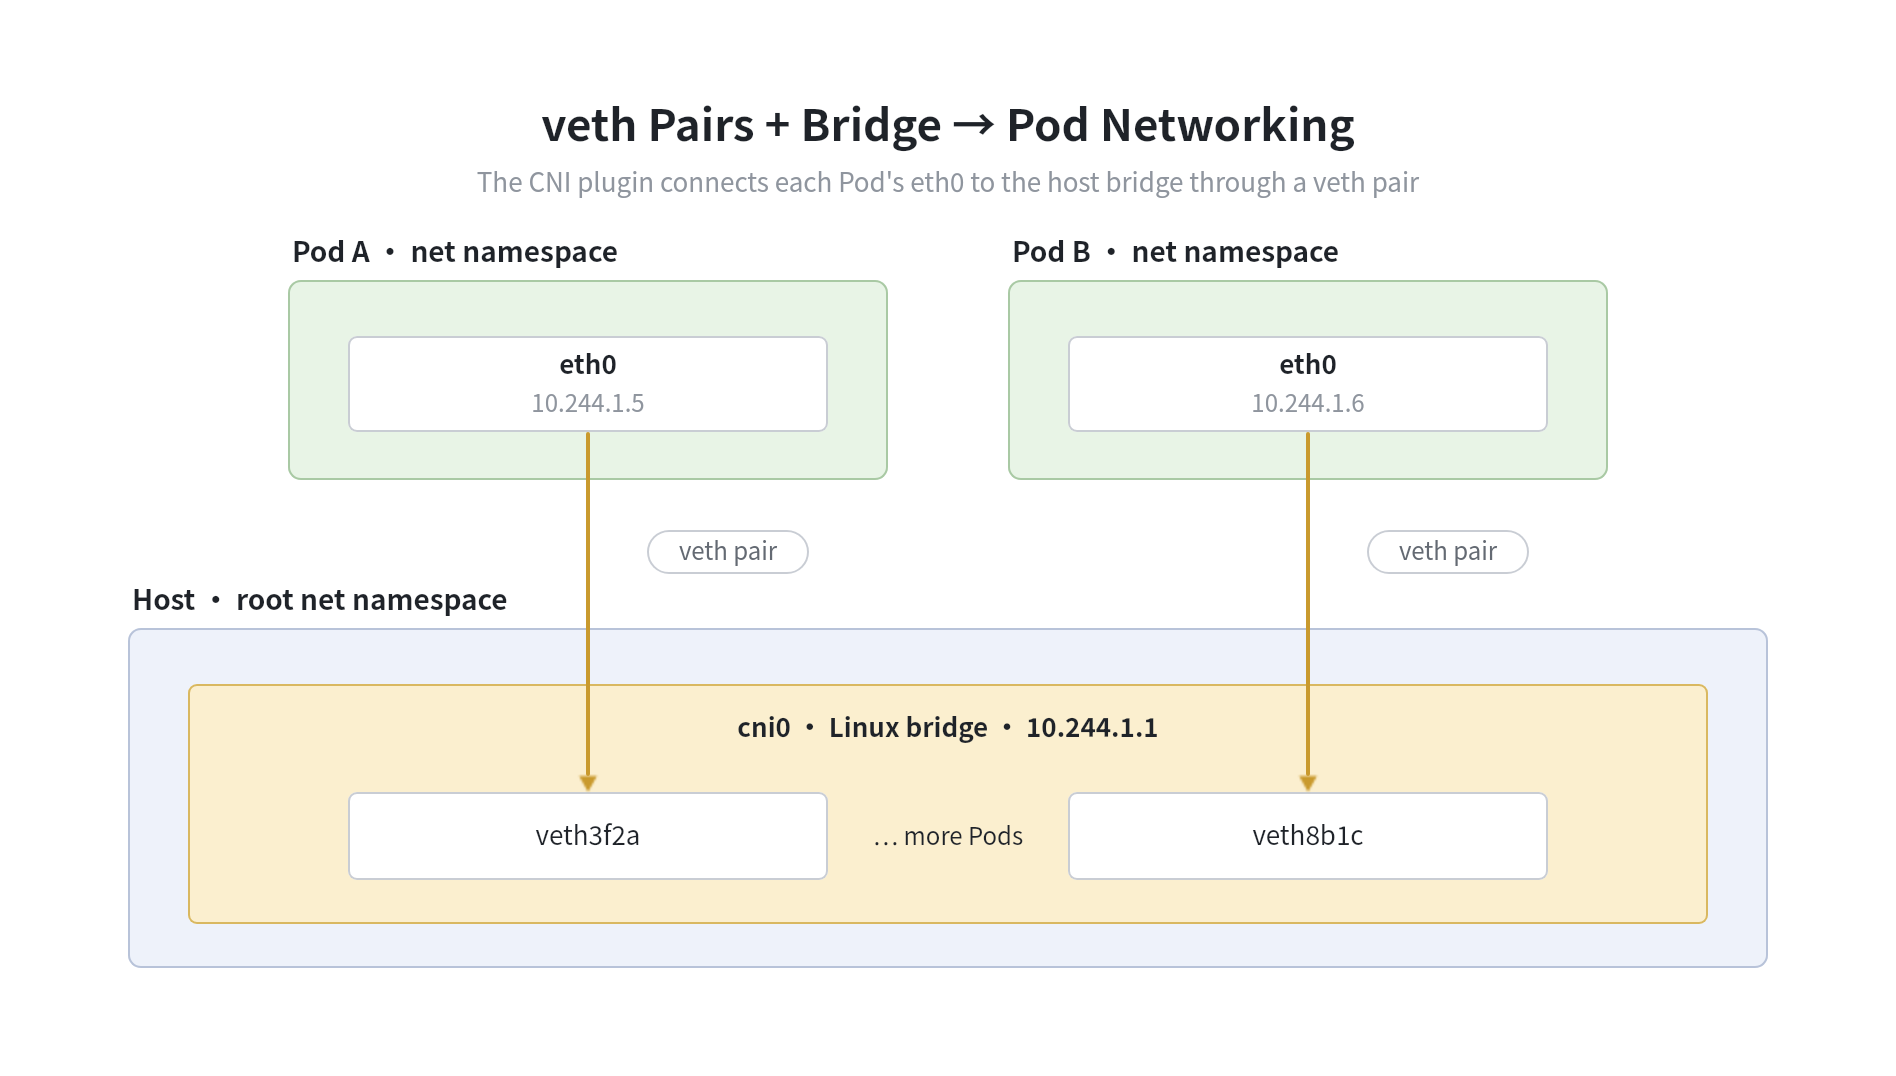
Step by step when a Pod is created:
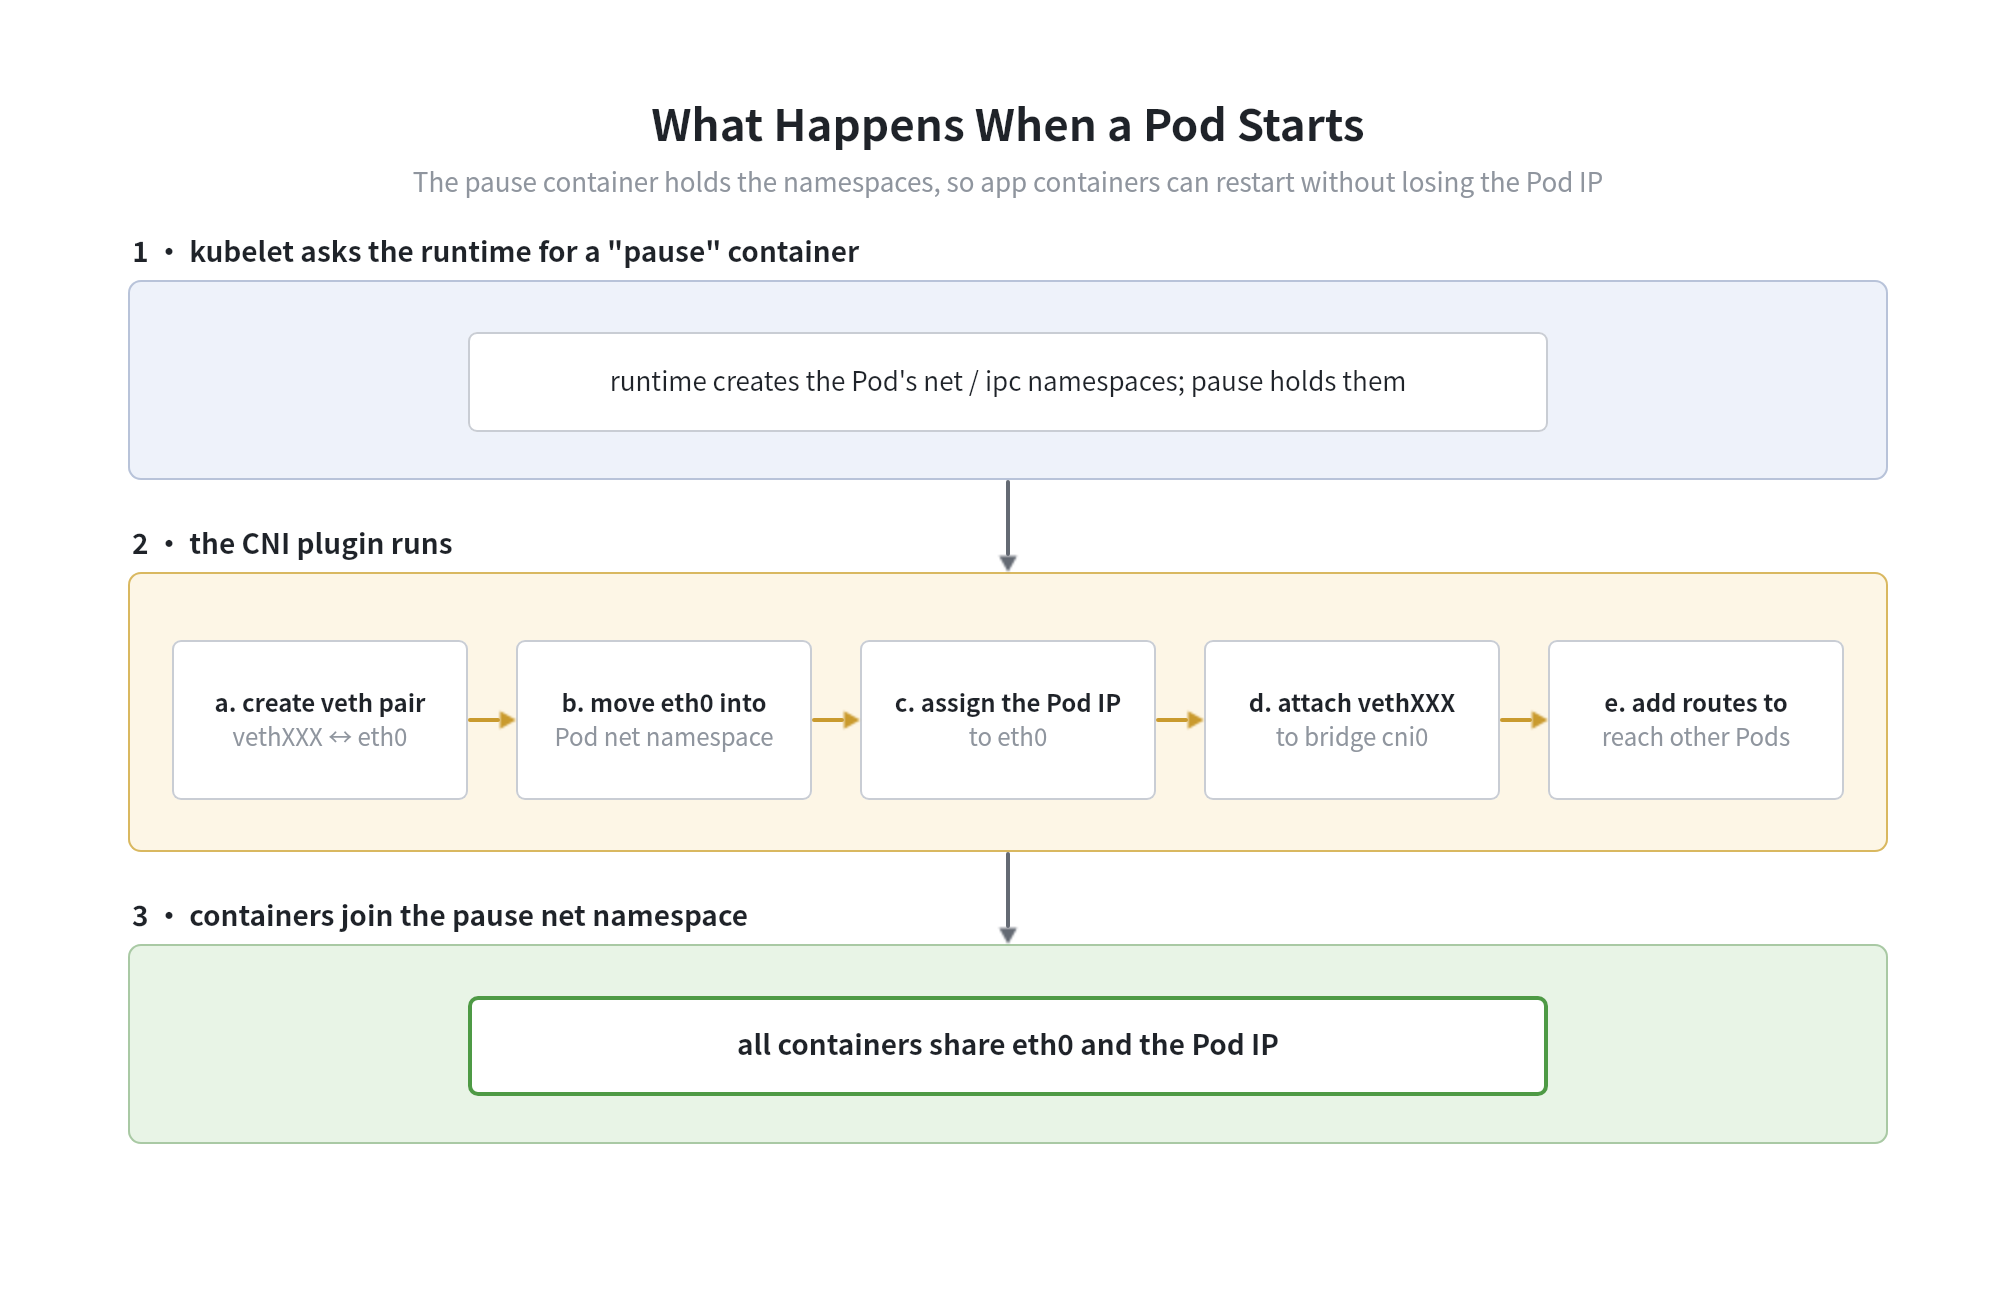
The pause container is the invisible container you never write — its only job is to hold namespaces so app containers can restart without losing the Pod’s IP.
overlayfs → container image layers#
Container images are stacked read-only layers. overlayfs merges them into one coherent filesystem:
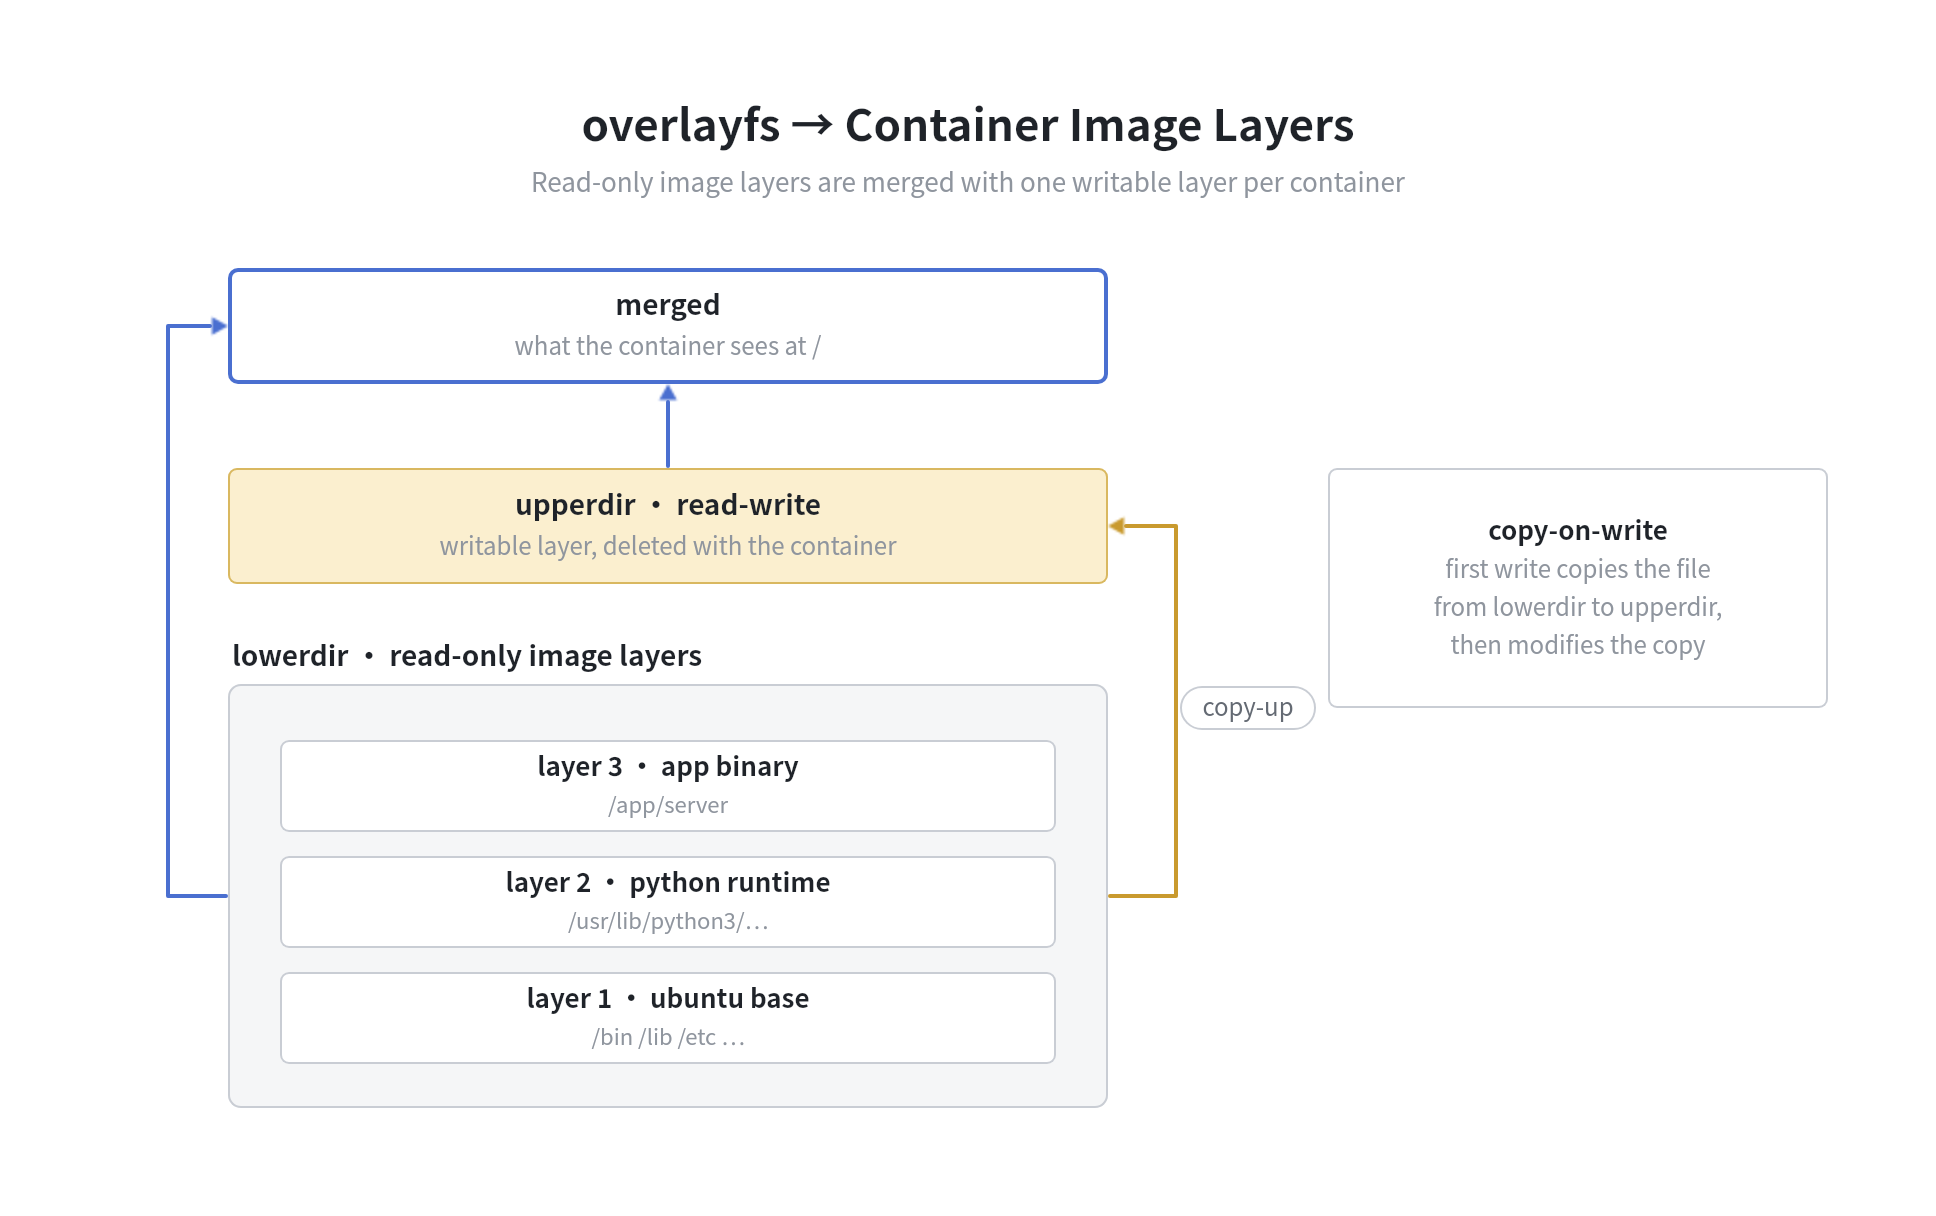
This is why:
- Multiple containers sharing the same image use almost no extra disk — they share lowerdir
- Container writes are ephemeral — upperdir is deleted when container dies
- PersistentVolumes mount into the container bypassing overlayfs entirely
iptables → Service (ClusterIP)#
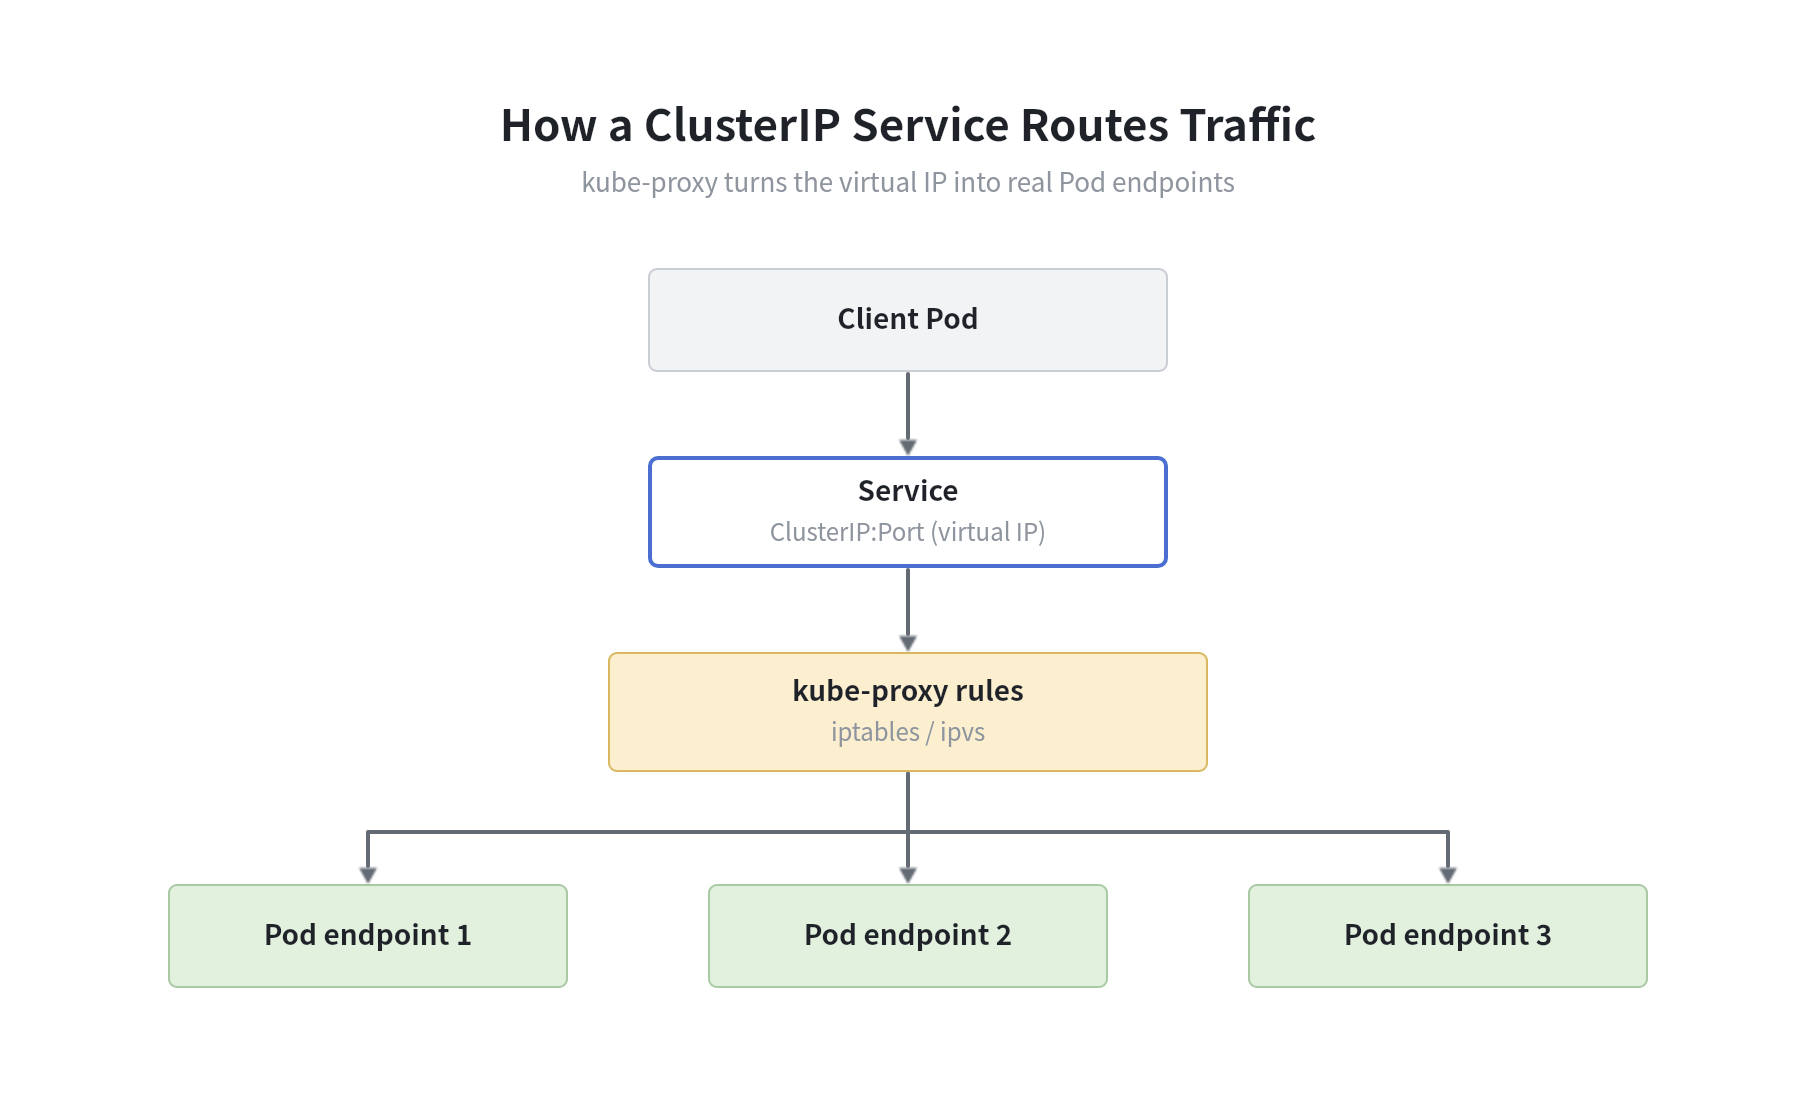
kube-proxy programs iptables rules to implement Service load balancing. When you create a Service:
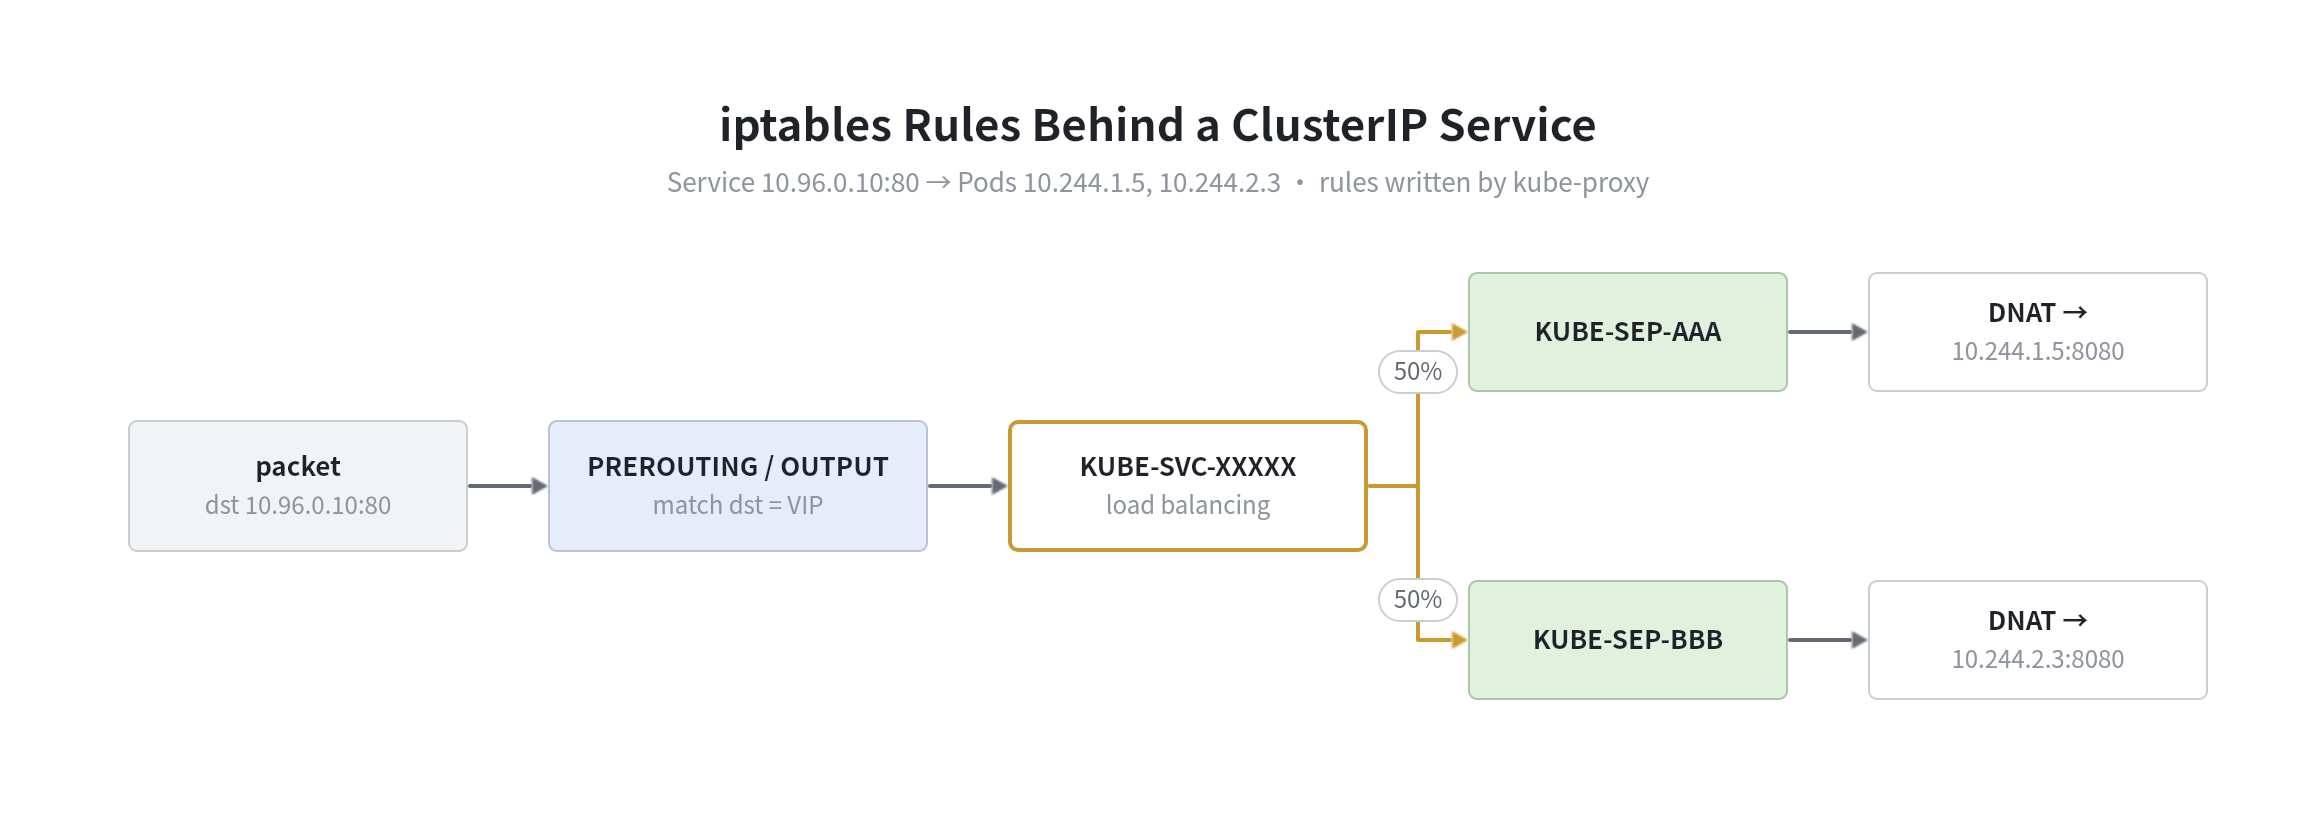
Dry run — packet flow for a ClusterIP request:
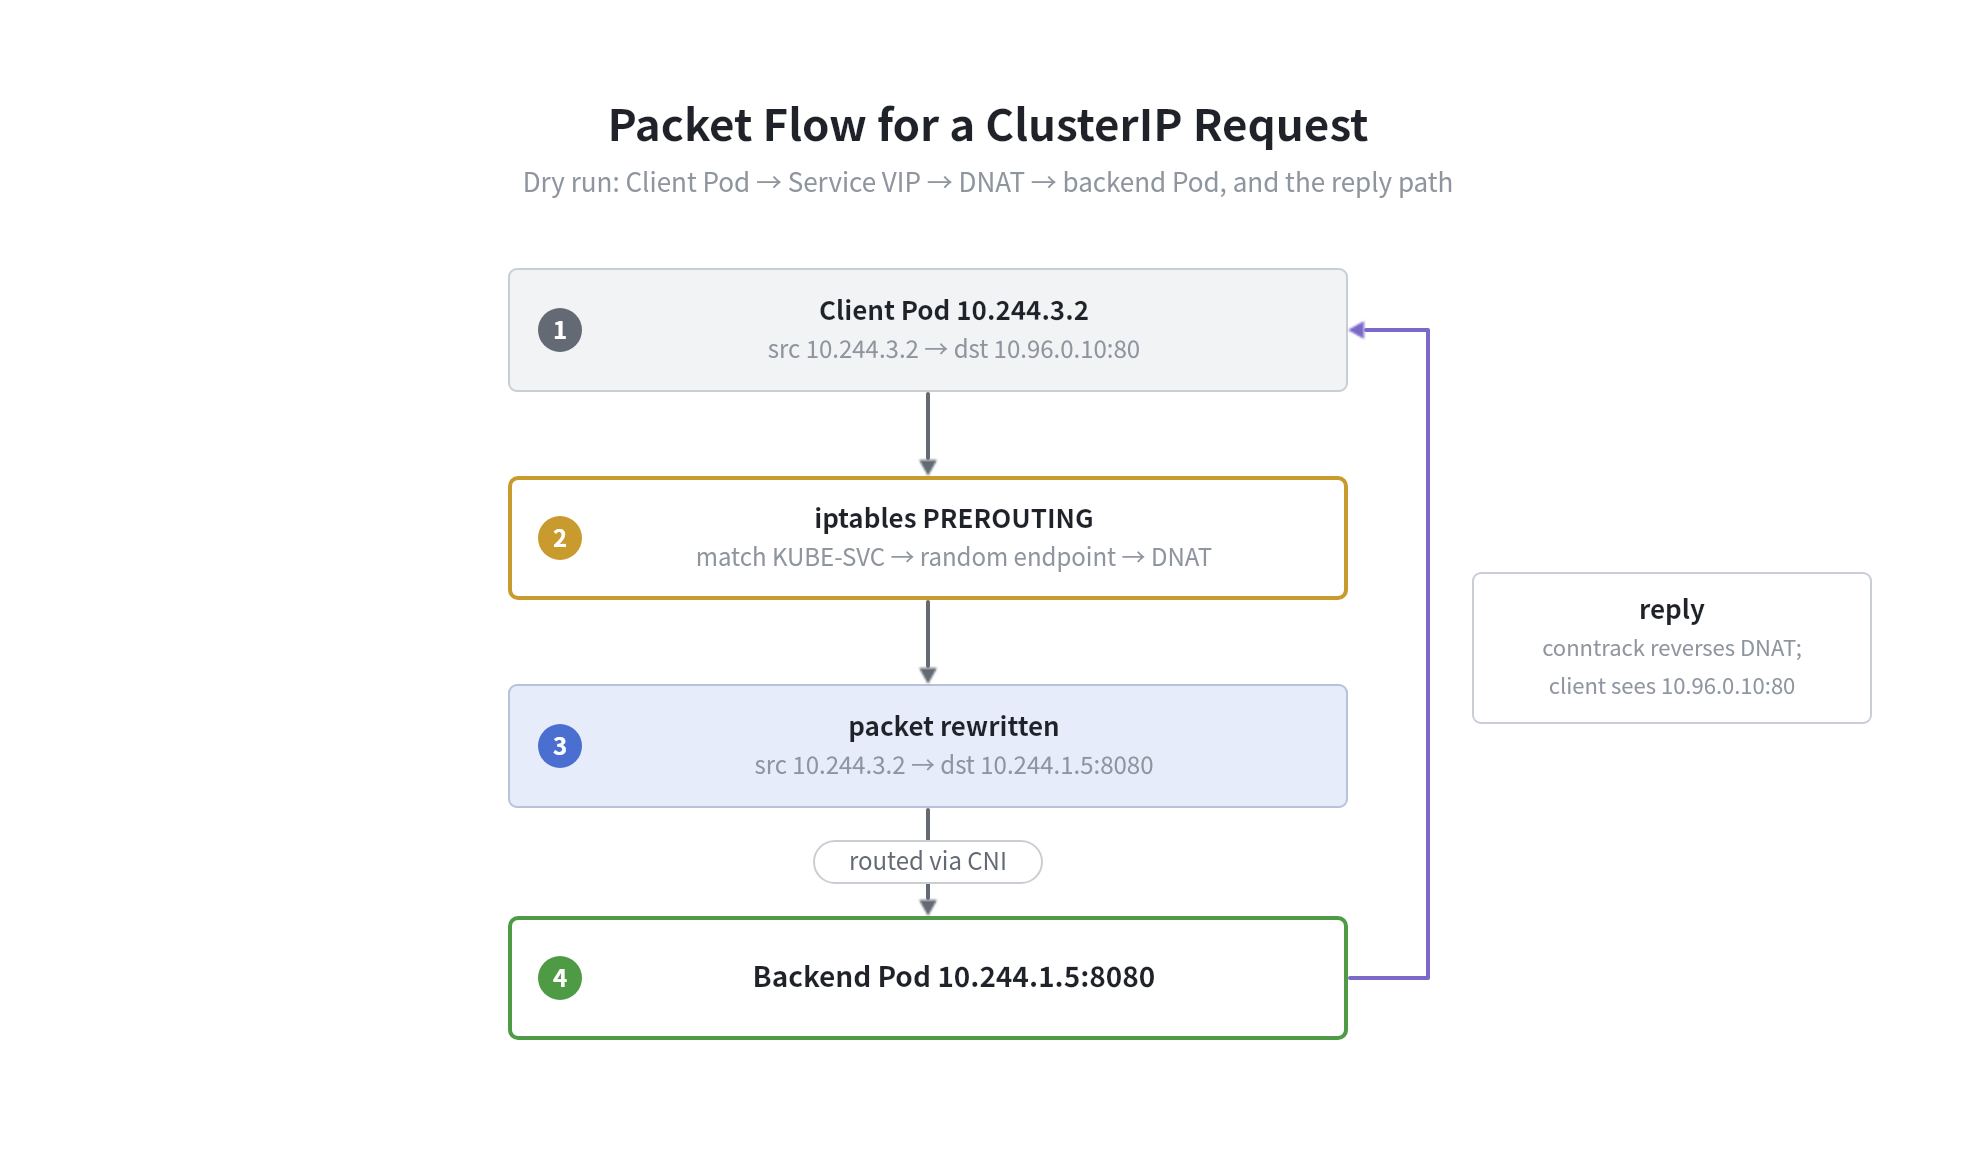
kube-proxy has three backend modes:
| Mode | Mechanism | Lookup | Status |
|---|---|---|---|
| iptables | netfilter rules, random selection | O(n) | default, stable |
| ipvs | kernel virtual server table | O(1) | stable, better for large clusters |
| nftables | successor to iptables, atomic rule updates | O(n→better) | beta since k8s 1.31 |
Summary: k8s abstraction → Linux primitive#
Pod Lifecycle#
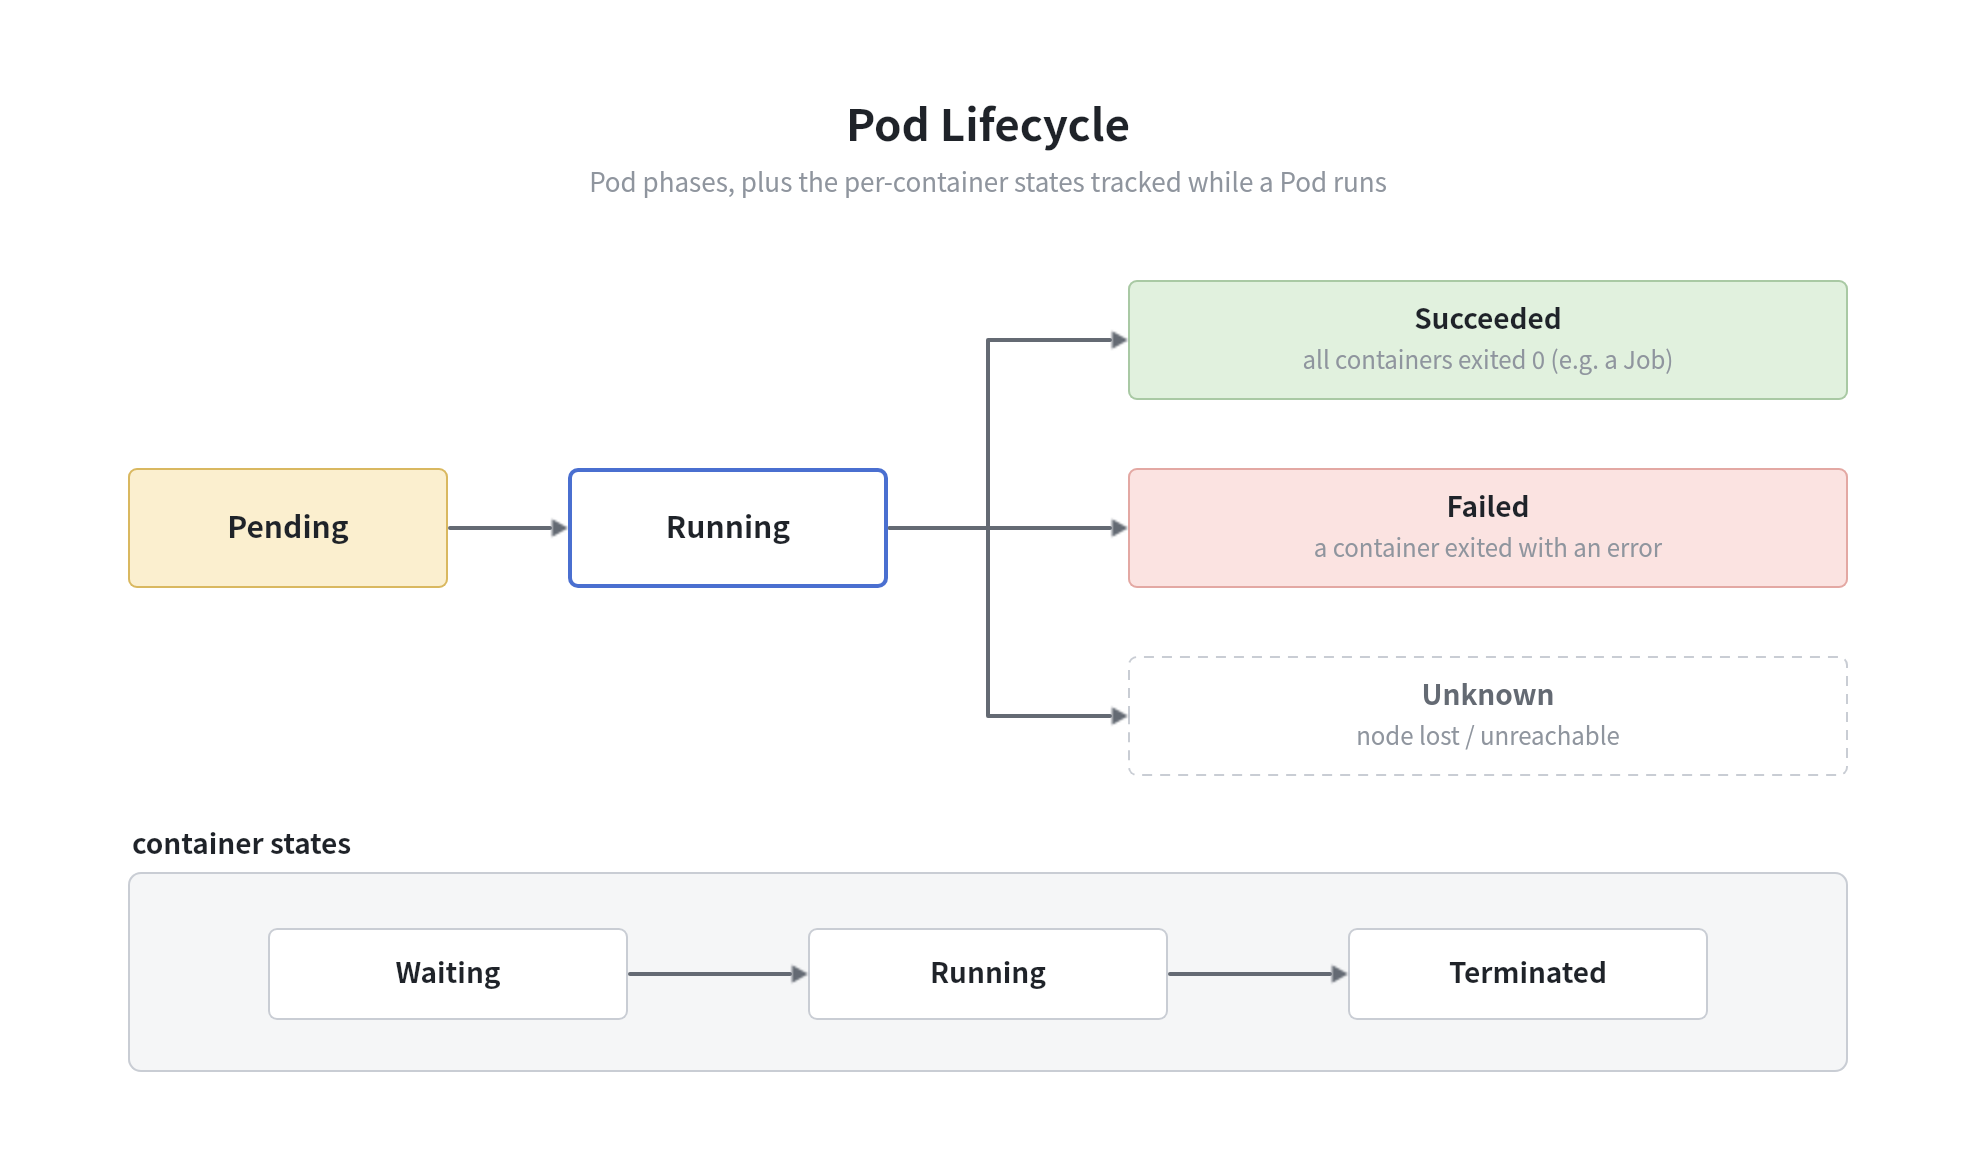
Probes that kubelet runs:
- livenessProbe — is the app alive? Restart container if it fails
- readinessProbe — is the app ready to serve traffic? Remove from Service endpoints if it fails
- startupProbe — has the app finished starting? (for slow-starting apps)
Scheduling#
The scheduler picks a Node for each new Pod in two phases:
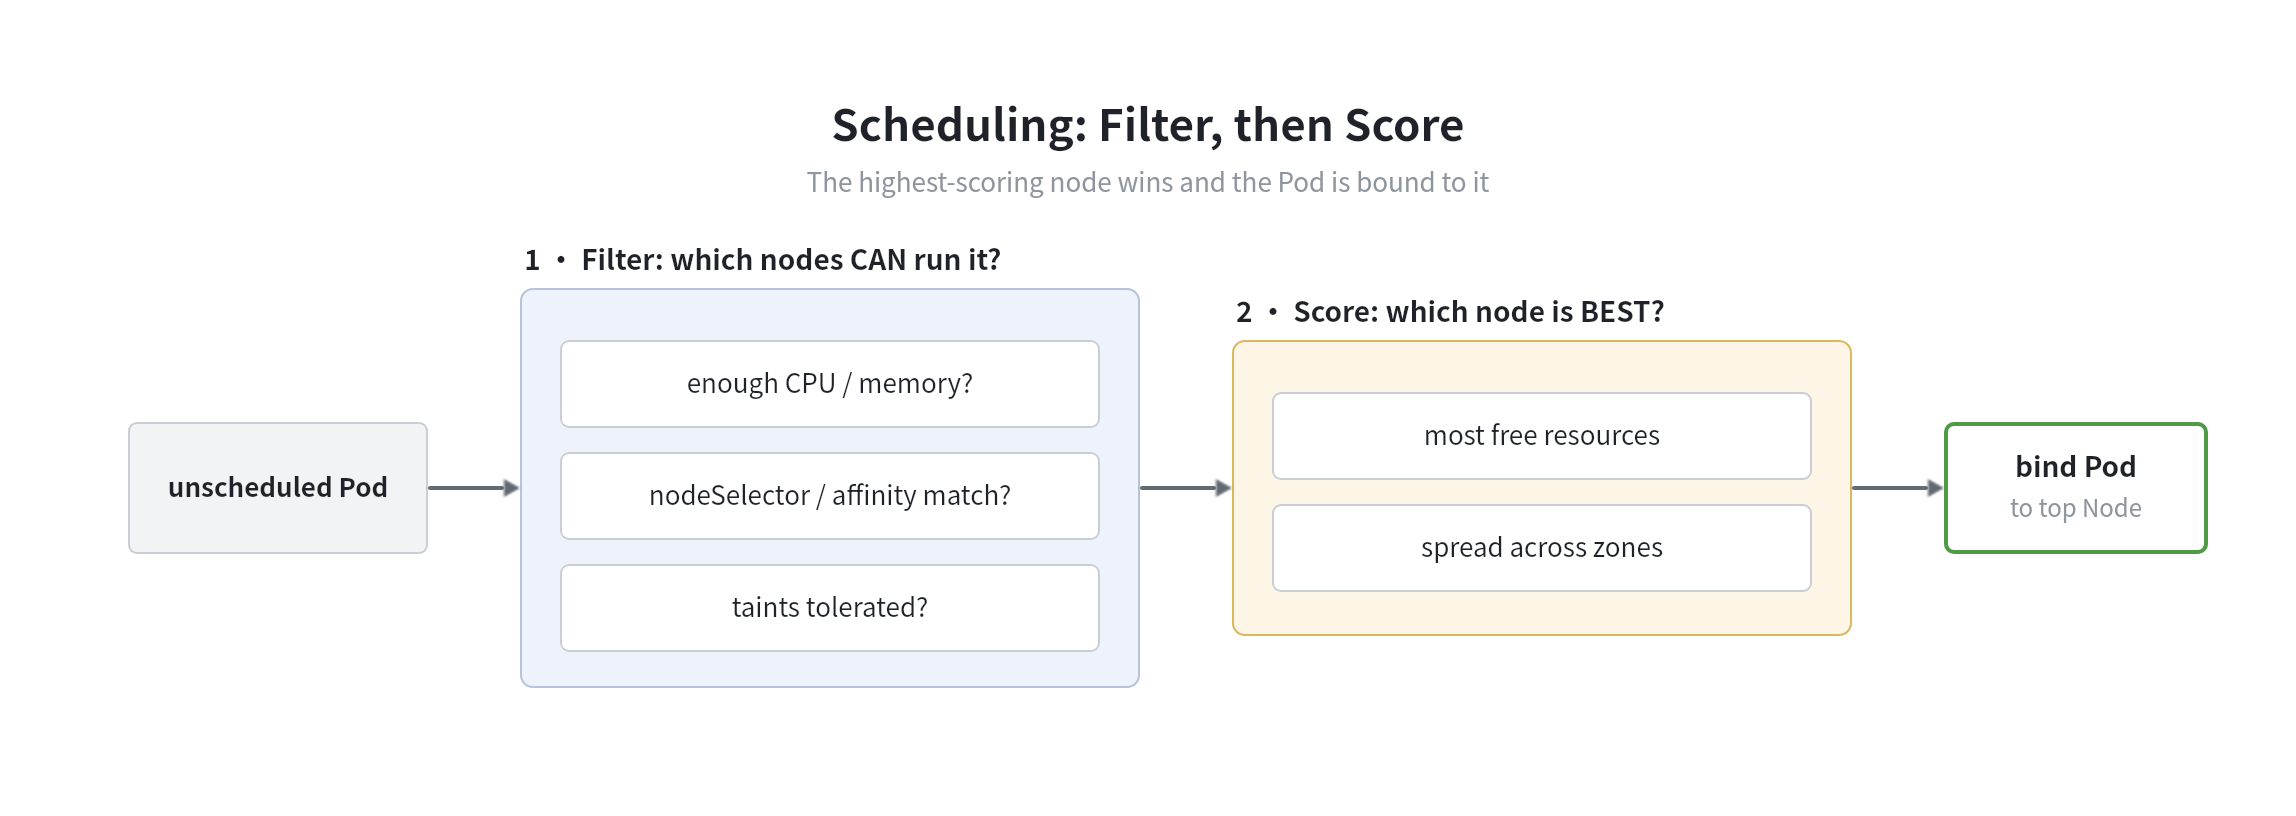
Key scheduling controls:
| Mechanism | Purpose |
|---|---|
resources.requests/limits |
Reserve and cap CPU/memory per container |
nodeSelector |
Pin Pod to nodes with specific labels |
affinity/antiAffinity |
Soft/hard rules for co-location or spreading |
taints & tolerations |
Mark nodes as special (GPU, infra); Pods must tolerate to land there |
Networking Model#
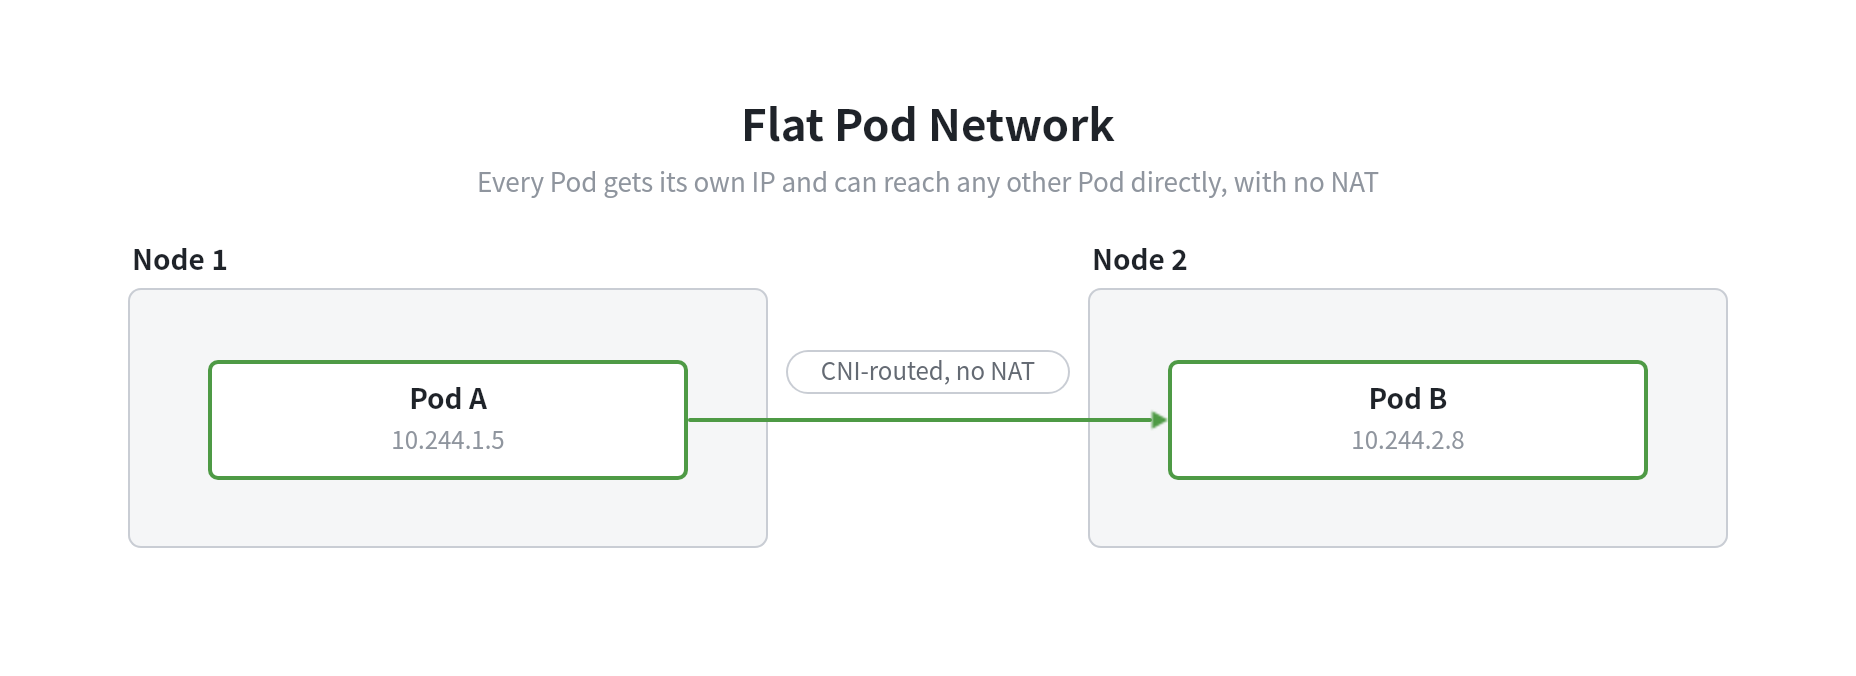
k8s mandates a flat network:
- Every Pod gets its own IP
- Any Pod can reach any other Pod directly (no NAT)
- Implemented by a CNI plugin (Flannel, Calico, Cilium, etc.)
Service networking (how ClusterIP works):
Rolling Updates#
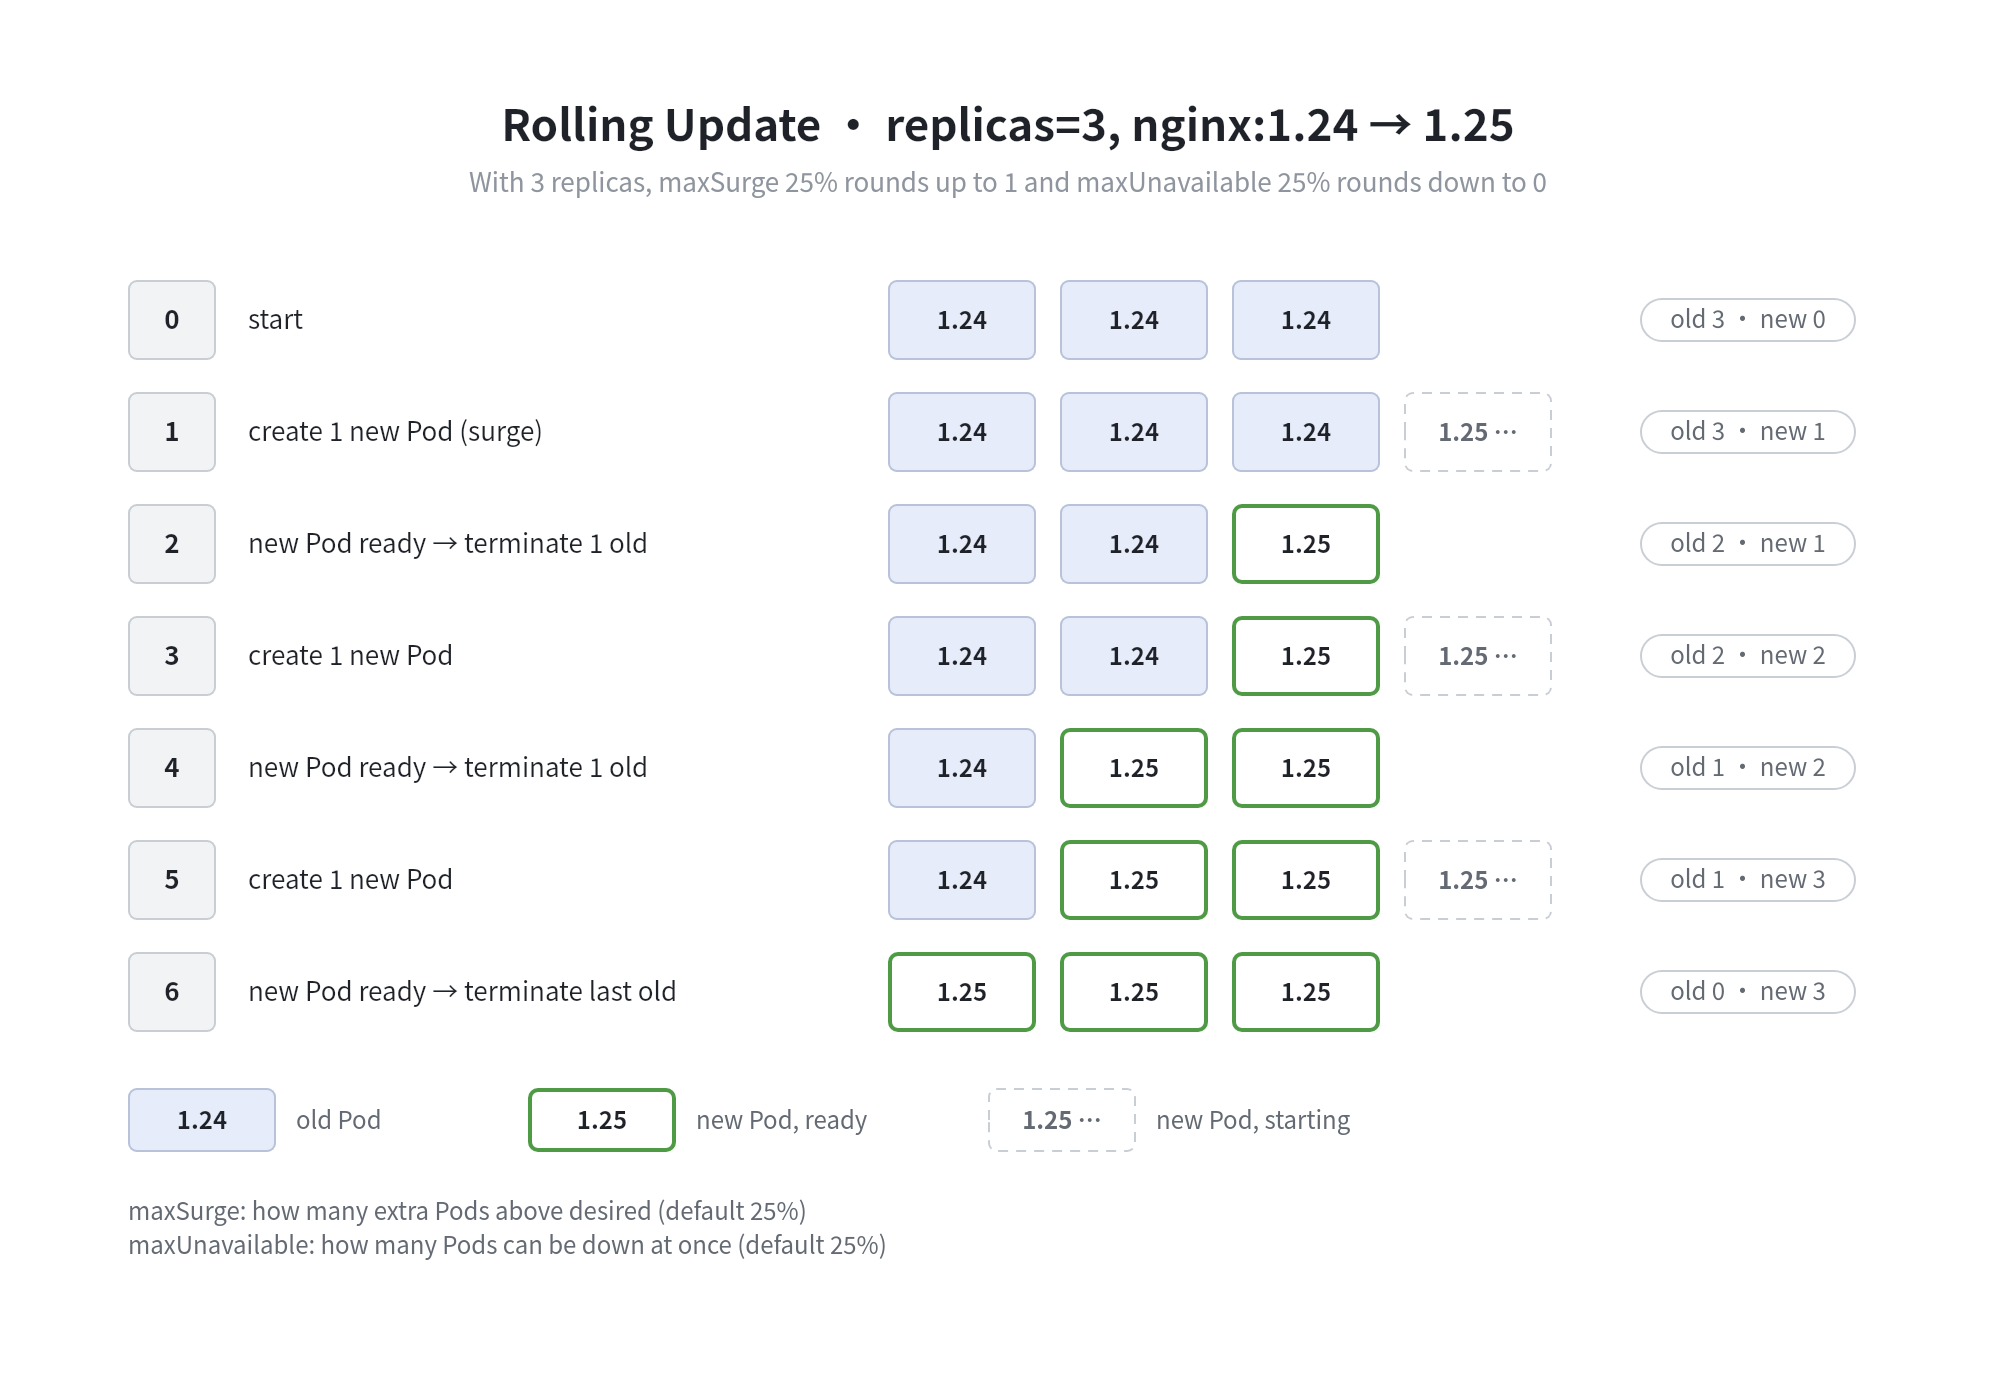
Rollback is instant — Deployment keeps previous ReplicaSet around:
kubectl rollout undo deployment/nginx
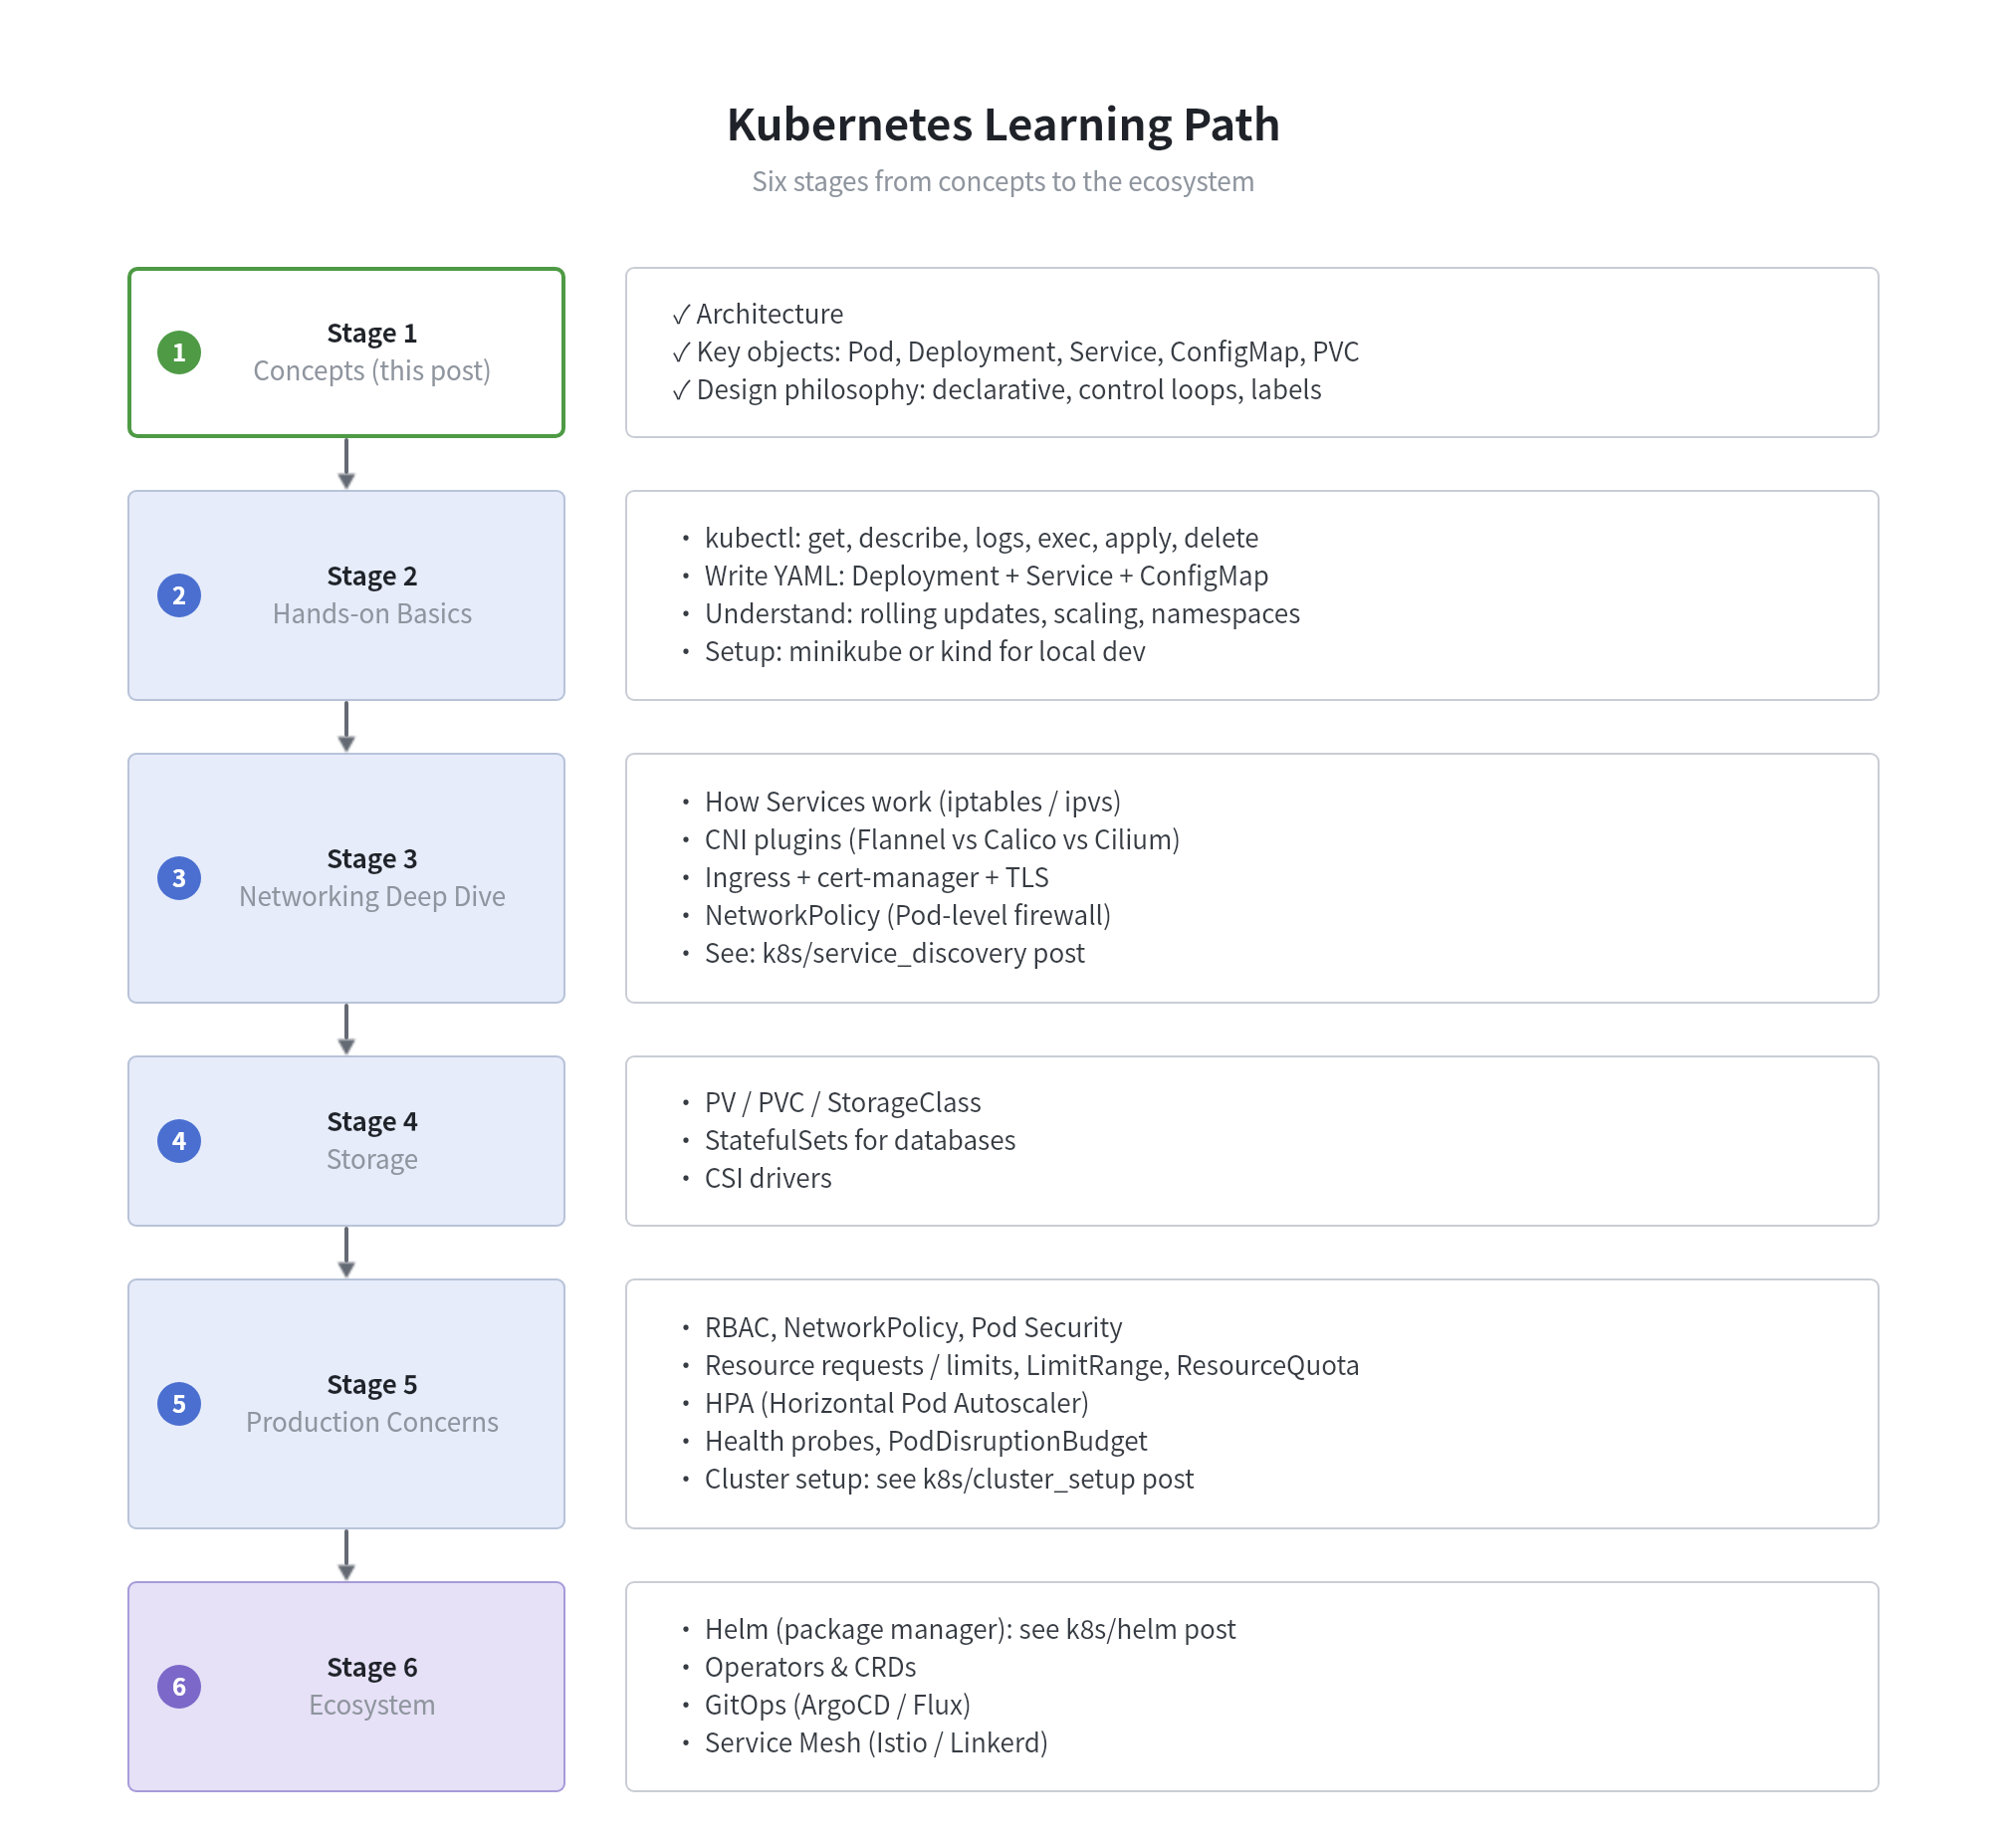
Learning Path#
References#
Official Kubernetes Docs
- Cluster Architecture
- Components overview
- Workloads (Pod, Deployment, StatefulSet…)
- Services & Networking
- Gateway API
- Storage (PV/PVC/StorageClass)
- RBAC
- Pod QoS classes
- Resource requests & limits
- Pod lifecycle
- Scheduling (affinity, taints)
- User Namespaces (beta k8s 1.30)
- cgroups v2 (GA k8s 1.25)
- CNI (cluster networking)
- kube-proxy & nftables
Linux Fundamentals
- Linux namespaces (man 7 namespaces)
- cgroups v2 kernel docs
- veth devices (man 4 veth)
- overlayfs kernel docs
- netfilter / iptables
Recommended Reading
- Kubernetes in Action (Marko Luksa) — best book for deep understanding of k8s internals
- Container Security (Liz Rice) — Linux primitives (namespaces, cgroups, seccomp) under containers
- Gateway API docs — successor to Ingress, GA since 2023
- Kubernetes blog — release notes and deep-dive posts per version
Comments